Article schema is structured data that describes one article: what it is called, who wrote it, when it was published, and which image represents it. Structured data is the format, usually JSON-LD, that carries those facts in a way a crawler can read without guessing. Google’s article structured data documentation, updated 8 September 2026, says this markup can help Google understand the page and show better title text, images, and dates. It also says there are no required properties. You add the ones that apply. A plugin that injects every type it knows is not following that instruction.
Repeat the page. Do not invent a richer one. Use Article or BlogPosting for a guide. Set the headline, the author, and the dates to what a reader already sees. Leave out FAQ and HowTo markup that exists only to chase a rich result. Those displays are gone. The paragraph is still what gets quoted.
What article schema is
Structured data is a caption for the page, written for machines. The article is still the HTML. Google’s article page says the markup can make the title, the image, and the date clearer in Search, Google News, and the Google Assistant. It does not say the markup is what makes the page worth ranking. A valid graph on a thin page is a valid description of a thin page.
JSON-LD is the form to use on a blog. It sits in a script block and does not change what the reader sees. That is also its risk. Because the reader never sees it, it is easy to let it drift from the byline, the H1, and the date on the page. Microdata buried in the template has the same problem if two systems both write an author. One article should have one description. Two author names that disagree are not “more structured.”
Google’s article documentation says to follow the general structured data guidelines, and it warns that violating them can lead to a manual action. The practical rule is the one those guidelines are for: mark up the content of this page, the content a person can see, and do not mark up something that is not there. A five-star aggregateRating on a how-to that has no reviews is that violation. So is an FAQ block that exists only inside the script.
There is no eligibility prize for filling every recommended field with a guess. The recommended properties are recommended when they apply. The Rich Results Test can flag syntax. It cannot tell you that the author is fictional. Read the page, then read the JSON.
Article, BlogPosting, or NewsArticle
Google supports three types for this feature: Article, NewsArticle, and BlogPosting. BlogPosting is a kind of article. For a guide on a company site, Article or BlogPosting both say what the page is. NewsArticle says the page is news. Use it when you are publishing news. Do not use it on an evergreen procedure because a template defaulted to it, or because someone hoped it would qualify the URL for Top stories.
Google is explicit that article markup is not required to be eligible for Google News features such as Top stories. Adding NewsArticle does not create that eligibility. It tells Google the page is a news article. If the page is a standup procedure that will still be true next year, that statement is false.
TechArticle is a schema.org type some templates use for technical guides. Google’s article feature lists Article, NewsArticle, and BlogPosting. A technical guide can be an Article or a BlogPosting and still be technical. If you use a more specific type, keep the same properties and the same match to the page. The type is not a keyword.
One page, one main article object. A tag archive is not an article. A thank-you page is not an article. A 404 template is not an article. Do not emit article schema from a layout that wraps every URL, including the ones a robots meta tag is trying to keep out of results.
Properties worth including
Google’s table of recommended properties is short. These are the ones that apply to a normal post.
| Property | What it should say | What goes wrong |
|---|---|---|
headline |
The title of the article, concise enough not to be cut off for no reason | A keyword list that does not match the H1. The title tag page is the promise. The headline should be that promise. |
author |
A Person or an Organization, with name and a url when you have a real page for them |
A made-up person, or several authors jammed into one name string. The author page is who may be named. |
datePublished |
When the article was first published, in ISO 8601, with a timezone if you know it | Replacing it with today’s date on every refresh |
dateModified |
When the article was last meaningfully updated, if you want Google to have that date | Moving it when only the template changed. The content refresh is the test. |
image |
A crawlable image that represents the article, not the logo | A blocked file, a decorative mark, or a picture of a different topic. Image SEO is the alt text and the filename. |
Google recommends a timezone on the dates. If you omit it, Google says it will default to the timezone Googlebot uses, which may not be yours. A date of 2026-10-06 is clearer than a datetime you copied from another site’s offset. Do not invent a minute-level timestamp you did not record. The date the reader sees is the one to match.
For the image, Google recommends a picture that represents the article, in a format Google Images supports, and for best results more than one high-resolution crop: 16:9, 4:3, and 1:1, each at least 50,000 pixels when you multiply width by height. Those crops are for how the image can be displayed. They are not a reason to upload three unrelated stock photos. One honest image is better than three that do not show the article. That same representative image is the file Discover can use as a thumbnail. The Discover guide is the size and the preview setting. The image URL has to be crawlable. A file blocked in robots.txt, or on a host Google cannot fetch, does not count.
author.name is only the name. Google’s author best practices say not to put the publisher, a job title, “posted by,” or “Dr.” inside the name. Job title and honorific have their own properties if you need them, and only if they are true and you are willing to show them. The publisher is a separate organization. Do not list two people as one string such as “Priya Shah, Northwind.” Each author is their own object. If the byline is the company, one Organization is the whole author.
The markup has to match the page
The failure mode is a second, more impressive article that exists only in the script.
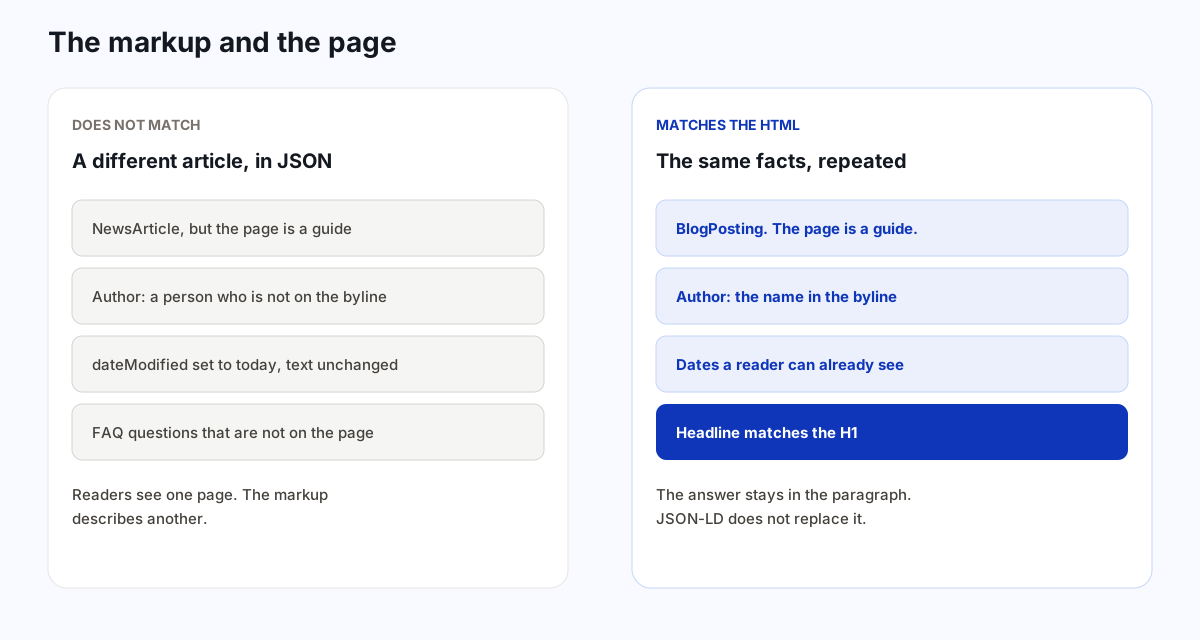
Check these pairs on one live URL. The H1 and headline. The byline and author.name. The visible published date and datePublished. The visible updated date and dateModified, when you show an updated date. The image on the page and image. If the page does not show an updated date, you do not need to pretend there was an update.
Google also describes author fields that help disambiguation: @type, and url or sameAs, pointing at a page that is actually about that author. An internal author page should be about that person. A link to the homepage for every author does not identify anyone. Person is for a person. Organization is for an organization. Do not use Thing, and do not mark a person as an Organization because the only URL you have is the company site. If the company is the author, say the company.
Multiple authors are an array of objects, and only the people who are actually presented as authors. A reviewer who checked a draft is not an author unless the page says they wrote it. A model is not an author. Disclosure that a model drafted a section belongs in the prose, where a reader would look, which is the point of the author-page guide. It does not become a second name in author.
FAQ and HowTo rich results
A lot of schema advice is a tour of rich results that Google has removed.
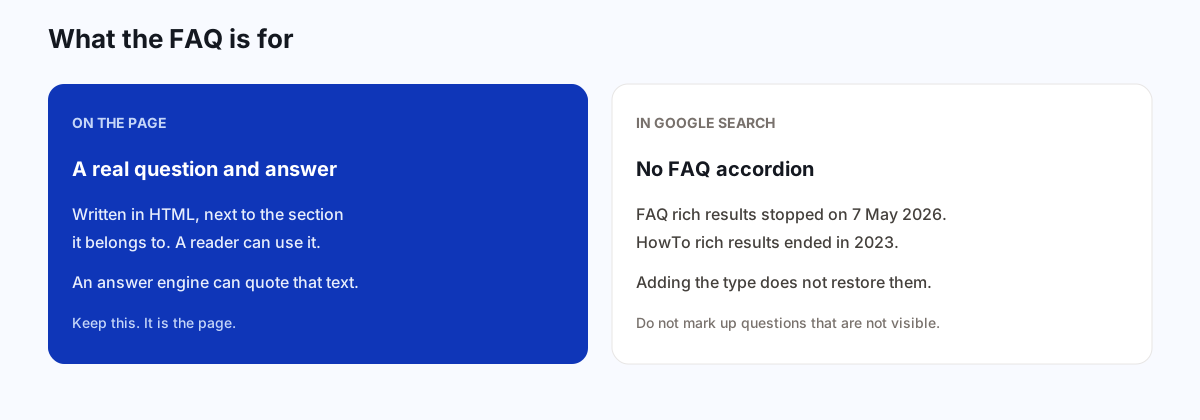
Google’s Search Central changelog says FAQ rich results stopped appearing in Google Search on 7 May 2026. The documentation for that feature was removed after that. In 2023, Google had already limited FAQ rich results to well-known government and health sites, and then removed HowTo rich results on mobile and desktop. HowTo rich results have not been a Search feature since September 2023. Adding FAQPage or HowTo to a company blog does not bring those displays back.
Unused markup is not a penalty by itself. Google said, when it narrowed those results, that structured data which is not used does not cause problems for Search and also has no visible effect. The reason to be careful is different. Markup that describes questions the page does not show is not “unused.” It is a description of content that is not there. If you keep a visible FAQ because readers need it, the questions and answers in any FAQ markup must be those same words. If you added the block only for an accordion, you can delete the markup. You can also delete the block if it does not help the reader. Do not keep a fake FAQ so a model has something to extract that the article never earned.
A visible question heading is still useful. Answer engines quote HTML. A short answer under a real question is a passage. That passage does not need a type that Google no longer displays. The answer engine guide is about the passage. This page is about not confusing that passage with a retired rich result.
QAPage is not a replacement. It is for a page with one question and answers that users can submit. A blog FAQ is not that page. Do not switch types to chase a different rich result.
Author and dates
The author field is where templates invent expertise. If the byline says BloGoose, the schema says BloGoose, as an Organization, with the site URL. If a person will stand behind the article, the schema names that person and links to a page about them. The author guide covers the choice. Schema does not make the choice true.
Dates are the other place templates lie. datePublished stays the first publication. dateModified moves when the article changed in a way you would tell a reader about. Google’s helpful-content questions flag changing dates without a substantial edit. The refresh guide uses Google’s sitemap note as the practical line: a change to the main content, the structured data, or the links can be significant. A copyright year is not. If you change the markup and not the article, you have not earned a new visible date. If you change the article, the visible date, dateModified, and the sitemap lastmod move together. The XML sitemap page is the file. This page is the article object.
ISO 8601 is the format Google asks for. 2026-10-06 or a full datetime with a timezone. A string such as “October 6th, 2026” in the JSON, while the HTML shows a different day, will not match. Write the date once and use it in both places.
Markup that does not belong
- Ratings the page does not show. Stars, review counts, and “rated 4.9” on a guide with no reviews are misleading markup.
- HowTo steps that are only in the script. If the page has steps, write them in HTML. The rich result is gone. The steps are for the reader.
- A FAQ that duplicates the whole article in slightly different words, added so the page looks more extractable. One real question is enough. Ten restatements are clutter.
- Breadcrumbs that are not on the page. If you show a breadcrumb trail,
BreadcrumbListcan repeat it. If the trail is not visible, do not invent one in JSON. The breadcrumb guide is which path to show, and the fact that the desktop rich result is not a mobile one. - A second graph from a plugin that names a different author or a different date than the template. View source and search for
"@type". One article object is the goal. - Speakable, about, and mentions lists stuffed with keywords the page does not discuss. Extra properties do not create topical coverage.
For a multi-part article, Google’s technical guideline is about the canonical: it should point at each part or at a view-all page, not at page one of a series while the other parts pretend to be the whole. Most blog posts are one URL. If yours is one URL, the canonical is that URL, which is the canonical tag decision. Schema does not pick a different canonical on the side.
Paywalled articles have their own markup if the body is behind a login. A public guide does not need it. Do not mark a free article as paywalled.
What an answer engine can use
An answer engine quotes text. JSON-LD can name the author and the date, which is useful context, and it can repeat a headline. It is a poor place to hide the only copy of the answer. If the script says the procedure has three prompts and the HTML never says that, a person does not see it, and a system that reads the visible article does not see it either. Put the claim in a paragraph. Let the schema name the page the claim is on.
Google’s note on AI features, reflected in the Search Central changelog for 15 June 2026, is that an llms.txt file is not needed for Google Search and does not change visibility or rankings there. The same idea applies here. A special file, or a special type, is not a substitute for the article. Other products may read a file you publish for them. Google Search still reads the page.
Schema is also small. A JSON-LD block is text. It does not need a JavaScript library, a tag manager, or a third-party renderer to exist. WebSite markup for the site name belongs on the home page only, which is the site names guide. Put the article markup in the HTML response so it does not depend on a script finishing. A script can inject JSON-LD, and it can also fail. The JavaScript SEO guide is why the response should already contain the article and the markup. If a separate mobile URL exists, its structured data has to match, with mobile URLs in the mobile markup. The mobile-first indexing guide is that case. A page that waits on a widget before the article text appears is a slower page and a harder page to quote. The markup should not be the thing that makes the article late.
An article schema example
Northwind’s standup guide shows this on the page: H1 “How to run an async standup.” Byline “By Priya Shah,” linking to her author page. Published 4 March 2026. Updated 6 October 2026, after the cutoff-time step was rewritten. The image is the thread layout the procedure describes.
The JSON-LD uses BlogPosting. headline is “How to run an async standup.” author is a Person, Priya Shah, with the URL of her author page. datePublished is 2026-03-04. dateModified is 2026-10-06. image is that diagram, on a URL Google can fetch. The publisher is Northwind, the organization, not Priya’s name repeated as the publisher.
What they removed: a NewsArticle type left over from a theme, an aggregateRating of 4.8 with no reviews, a HowTo that copied the three steps into JSON while the HTML already had them, and an FAQ whose questions were not on the page. The three steps stayed in the article, as HTML. One real question stayed at the bottom, in HTML, because readers ask what to do when someone misses the cutoff. They did not add FAQ schema to get an accordion. That accordion is not available.
How this shows up in a BloGoose draft
When you review a draft, compare the byline you will publish with the author the schema will name. If the draft has no person who will sign it, the author is your organization. Do not let a template fill in a stock name. Compare the H1 with the headline field. Compare the dates with the refresh you actually did. If the draft includes FAQ schema, every question must be visible in the article, word for word, and you should know you are describing the page, not buying a rich result.
The content brief is where you decide the promise, the author, and the claims before the JSON exists. Schema written after the article, by copying the article, stays honest. Schema written first, to satisfy a checklist of types, is how the JSON and the page diverge.
Questions about article schema
What is article schema?
Article schema is structured data that describes an article: the headline, the author, the dates, and a representative image. Google supports Article, NewsArticle, and BlogPosting. There are no required properties. Add the ones that match the page.
Does structured data improve rankings?
Structured data helps Google understand the page. It does not replace the article, and Google does not guarantee that a search feature will appear because the markup is valid. Mark up what a reader can see. Do not add a type to chase a result Google no longer shows.
Should a blog post use NewsArticle?
Use NewsArticle when the page is news. A guide or a company blog post fits Article or BlogPosting. NewsArticle does not make an evergreen how-to eligible for a news feature. Google says article markup is not required for Google News features such as Top stories.
Do FAQ rich results still appear?
No. Google’s Search documentation says FAQ rich results stopped appearing in Google Search on 7 May 2026. A visible FAQ can still help a reader. Markup that repeats it does not produce an accordion in the results. HowTo rich results were removed earlier, in 2023.
Should the author in the schema match the byline?
Yes. If the page says the organization wrote it, the author field should be that organization. If it names a person, the schema should name that person and can link to their author page. Do not invent a person so the markup looks more expert.
When should dateModified change?
Change dateModified when the article itself changed, and keep it aligned with the date the reader sees. Do not move it because you want the page to look new. The content refresh guide is the test for a substantial update. datePublished stays the first publication date.
Publish the article first. Let the schema describe that article.
Start the 1-day trial