A robots meta tag tells crawlers how one HTML page may be indexed and shown. noindex is the value that asks Google not to show that URL in search results. Google’s specification, updated 24 March 2026, says these rules are read only if the crawler is allowed to fetch the page. A line in robots.txt that blocks the fetch does the opposite of what people expect: the noindex is never seen, and the URL can still appear. This page is that distinction. It is not the Indexing API setup, and it is not the editorial choice of which article to keep. Those are the indexing setup and the content audit.
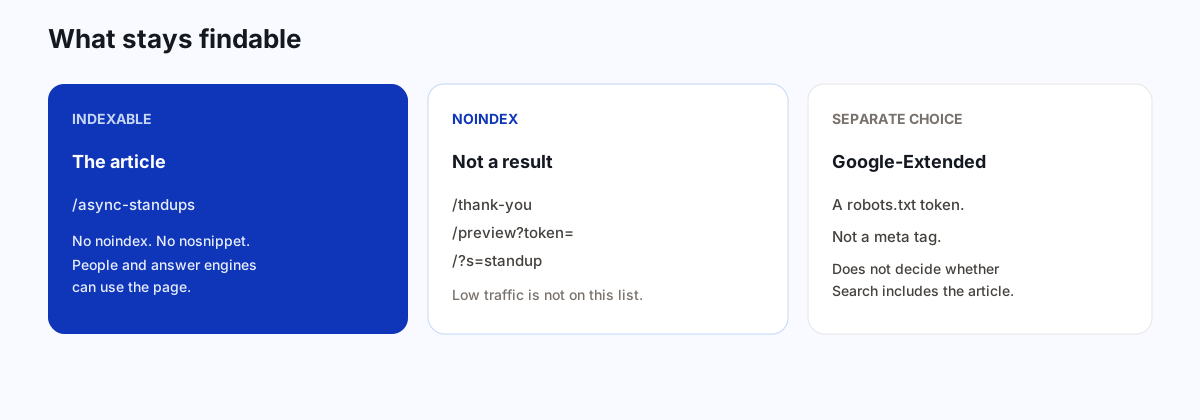
Let Google crawl the page, then say whether it may be a result. Use noindex for a thank-you page, a preview, or on-site search. Do not use it on an article you want found. Do not disallow that article in robots.txt. Google-Extended, if you use it, is a separate robots.txt token and does not replace either choice.
What a robots meta tag is
The tag sits in the page, usually in the head:
<meta name="robots" content="noindex">
name="robots" applies the rule to crawlers that honor it. Google says the name and the content are case-insensitive. To speak to Google specifically, the name can be googlebot for text results or googlebot-news for news results. Other names in that attribute are ignored by Google. A meta tag aimed at a different company’s crawler is not a Google control, even if a blog told you to paste it.
If one tag says nofollow for all robots and another says noindex for Googlebot, Google combines the restrictive rules. That page is treated as noindex, nofollow for Googlebot. When two rules conflict, the more restrictive one wins. nosnippet beats max-snippet:50. You do not get the gentler rule because you also sent it.
Google’s documentation notes that Google Search will also respect a robots meta tag in the body, not only in the head. Put it in the head anyway. A tag injected at the bottom, or added by a script after load, is a harder thing to audit, and the specification says the rules are only useful if the crawler can see them. The same page warns that data-nosnippet should not be toggled on existing nodes with JavaScript, because extraction can happen before or after rendering. The indexing rule belongs in the HTML you send. If that HTML already says noindex, Google may skip rendering, so a script that tries to remove the tag may never run. The JavaScript SEO guide is that trap. A noindex that exists only on the mobile version can drop the page, because the smartphone crawl is the indexed copy. The mobile-first indexing guide is that mismatch.
For a PDF or another non-HTML file, the equivalent is an X-Robots-Tag HTTP header, not a meta element the file does not have. The header can carry the same rules. Most blog posts are HTML. The header matters when you are trying to noindex a file download, not when you are publishing an article.
noindex versus robots.txt
robots.txt and the robots meta tag answer different questions. Mixing them is the mistake that leaves thank-you pages in search results and hides articles you meant to publish.

Google’s robots.txt introduction says the file tells crawlers which URLs they can fetch. It is mainly there so a site is not overloaded. It is not a way to keep a page out of Google. A disallowed URL can still be indexed if another page links to it. The result may show the URL and anchor text from those links, without the content, because Google never fetched the content. To keep a URL out of results, Google’s instruction is noindex, or password protection, or removing the page.
The robots meta specification says the same thing from the other side. If robots.txt disallows the URL, the meta tag and the X-Robots-Tag header are never found, so they are ignored. If you need noindex to be obeyed, robots.txt must allow the crawl.
That is also why robots.txt is a bad canonical signal. The canonical tag guide covers it: a blocked copy can be indexed without its content, and Google cannot see that it is a copy. Use a redirect or a canonical tag. Do not disallow the duplicate and call that a preference.
Password protection is the control for something that must stay private, such as a staging site or a draft that contains unreleased material. noindex is a request to well-behaved crawlers. robots.txt is a request not to fetch. Neither one encrypts the page. If a person should not be able to open the URL, do not leave it on the public internet with a tag.
Which URLs should be noindex
On a blog, most URLs should be eligible for results. The exceptions are pages that are not answers.
| URL | Instruction | Why |
|---|---|---|
| The article | No noindex. Allow the crawl. Include it in the sitemap. | This is the page you want found and quoted. |
| Thank-you or receipt page | noindex, and leave it out of the sitemap. | It confirms an action. It does not answer a query. |
| Draft preview with a token | noindex, or do not make it public. | A preview that gets indexed competes with the real URL. |
| On-site search results | noindex. | Those URLs are queries, not documents you wrote. |
| Tag or category archive that only repeats post titles | Either give it a real introduction and a job, or noindex it. | A list with no explanation is not a second article. Canonicalizing it to a post is the wrong tool, as the canonical guide says. |
| An article with little traffic | Do not noindex it for that reason. | Use keep, update, merge, or leave in the audit. Leave is an editorial label. noindex is only if it should not be a result. |
The audit’s “leave” label is the closest editorial cousin. A utility screen should not get a keyword. Omitting it from the sitemap is not enough, because the sitemap is a weak hint and a link from anywhere else can still surface the URL. noindex is the instruction. Merging two articles is still a redirect, not a noindex on the one you like less. noindex on the URL you hope will win removes it from results. Google’s canonical documentation says not to use noindex as the way to pick a preferred URL inside the site. A URL that no longer exists is not a noindex case either. It should return a real 404, which is the soft 404 problem when the server still says 200. Page 2 of a blog is not a noindex case by default either. Each page of that list keeps its own canonical URL, which is the pagination choice.
On a very large site, a noindex URL is still fetched, so the request spends crawl time. Google will not move that time onto other URLs unless the host is already at its crawl capacity limit. The crawl budget guide is when that limit is real. A disallow of filter patterns you do not want fetched is the faceted navigation guide, and noindex on those URLs would still need a fetch. It is not a reason to hide articles.
unavailable_after is a different rule: do not show the page after a date you specify. Google says it then crawls that URL much less. It is for content that truly expires, not for an article you plan to refresh. A procedure you will update next quarter should stay indexable. Putting an expiry on it because the year in the title feels old is how you remove a page you still need. Update the page. The content refresh is the edit. The robots tag is not a calendar.
Snippets, AI Overviews, and what to leave quotable
nosnippet tells Google not to show a text snippet or a video preview for that page. A static image thumbnail may still appear. The robots meta documentation is explicit about scope: this applies to web search, Google Images, Discover, AI Overviews, and AI Mode, and it prevents the content from being used as a direct input for AI Overviews and AI Mode. max-snippet with a number caps how much text can be used, including as a direct input for those AI features, unless you have separately allowed a use through structured data or a license. max-snippet:0 is the same idea as nosnippet. max-snippet:-1 means Google chooses the length. max-image-preview:large is the separate setting that allows a large image preview, including in Discover. The Google Discover guide is why a normal article wants that preview, and why nosnippet is the wrong companion on a page you hope will be shown.
That is the GEO decision on an article, and it is usually “do not set the rule.” If you want a passage quoted, the page has to be allowed to supply the passage. nosnippet on a guide is a refusal. It also removes the ordinary snippet under the blue link, so the result is harder to judge. Use it when showing the text would be the problem, for example a page of personal data that must not be excerpted. Do not use it because you would rather an overview sent the click without quoting you. The overview can still exist. Your page will not be the input.
data-nosnippet is the narrower tool. On a span, div, or section, it keeps that chunk out of the snippet. Google says any value on the attribute is ignored, including false, so the attribute’s presence is the whole instruction. An unclosed tag can swallow the rest of the page. It does not stop structured data inside that element from being used. For a normal article, you rarely need it. Hiding the answer in data-nosnippet and hoping the meta description carries the click is the same mistake as putting the only copy of the answer in an image. The title tag page is where the snippet text should come from: the page itself, with a meta description as a backup summary.
Structured data is not turned off by a snippet limit, except for description fields on articles and similar creative works, which follow max-snippet. Recipe markup can still be eligible for a recipe result when the text snippet is limited. The practical rule for a blog: do not expect a robots tag to veto schema you deliberately published, and do not publish schema you do not want used.
Google-Extended is not a meta tag
Google-Extended is a token in robots.txt. Google’s common-crawlers documentation describes it as a standalone product token. Publishers can use it to manage whether content Google crawls may be used to train future Gemini models that power Gemini Apps and Vertex AI, and for grounding in Gemini Apps and Grounding with Google Search on Vertex AI. Grounding, in that description, means providing content from the Search index to the model at prompt time. Google-Extended does not have its own HTTP user-agent string. Crawling is done with existing Google user agents. The token is a control in robots.txt, not a second bot you will see in the logs under that name.
Google says this control does not affect inclusion in Google Search and is not a ranking signal. Blocking Google-Extended is not noindex. Blocking Googlebot is not Google-Extended. A robots.txt group that disallows everything for Googlebot, written because someone wanted to “opt out of AI,” can remove the site from Search. A group that disallows Google-Extended and still allows Googlebot leaves Search alone and refuses that training and grounding use.
You cannot set Google-Extended in a robots meta tag. Google only documents googlebot and googlebot-news as user-agent tokens in the meta name. Names it does not list are ignored. Other companies publish their own crawler tokens for robots.txt. Those tokens are their policy, not Google’s, and a crawler may ignore robots.txt. If a page must not be readable, protect it. Do not treat a list of AI bot names as a lock.
For an article you want cited in ordinary search and in answer engines, the default is: allow Googlebot, do not noindex, do not nosnippet. Decide Google-Extended as a site policy, once, with the knowledge that it is about later training and specified grounding uses, not about whether this URL can rank. The answer engine guide is how you write a passage worth quoting. This page is how you avoid switching that passage off.
Rules that are easy to misuse
nofollow on a robots meta tag means “do not follow the links on this page.” It is not the same as rel="nofollow" on one anchor. Link-level nofollow, sponsored, and ugc are explained in citing sources. A page-level nofollow on an article throws away every internal link on that article as a discovery path. You almost never want that on a guide. You might want it on a page full of untrusted links you do not want used as a map.
none means noindex, nofollow. all means no restrictions, which is already the default, so writing it does nothing. noimageindex asks Google not to index the images on that page. It is not a substitute for alt text. If the images should be understood, describe them. The image SEO guide is that work. noimageindex is for a page whose pictures should not become image results.
notranslate asks Google not to offer a translated title and snippet. Use it when a machine translation of the result would be actively wrong, not as a default on an English blog. indexifembedded only matters together with noindex: it lets Google index the content when the page is embedded in another page, such as an iframe, even though the URL itself is noindex. A blog post does not need that pair.
Two older rules are on Google’s list of things it does not use. noarchive used to control a cached-link feature that no longer exists. nocache is not used. Adding them does not create a cache button or remove one. nositelinkssearchbox is also unused, because that feature is gone. A plugin that still emits noarchive is not protecting you. Check what else it emits. noindex is the one that changes whether the URL is a result.
Do not hide a page because traffic dipped
A URL with fewer clicks than last quarter is not a robots problem. The query may have been answered on the results page. The article may be stale. Another URL of yours may have taken the same job. Those are audit labels: keep, update, or merge. noindex is what you do when the URL should not have been a result. Using it to “clean up” a traffic chart removes the page from the set of pages that can earn the query later, including after you fix it.
There is a related helpful-content question about deleting a lot of older content mainly to look fresh. noindex-ing a large set of real articles in an afternoon is the same impulse with a meta tag. A single thank-you page is a precise noindex. Forty useful posts are not.
After you add or remove noindex, wait for a recrawl. The URL does not vanish from results in the minute you save the template. Search Console’s page indexing report is where you later see “Excluded by ‘noindex’ tag,” which is the tag working, or a URL you thought was indexable sitting in that bucket, which is the accident. Do not request indexing on a URL you just marked noindex and then wonder why it will not stay in the index.
A robots meta example
Northwind’s article at /async-standups has no robots meta tag, which means the default: indexable, links may be followed, a snippet may be shown. It is in the sitemap. robots.txt allows it. The title and the H1 match, which is the title tag problem, not this one.
/thank-you is the page after someone books a demo. It is noindex, it is not in the sitemap, and robots.txt does not disallow it, so Google can fetch the tag and honor it. /preview URLs that staff use to read a draft carry noindex. When the draft becomes /async-standups, the public URL does not copy the preview’s robots tag. That copy-paste is how a finished article ships hidden.
Northwind’s robots.txt does not contain Disallow: / for Googlebot. If they decide to opt out of Google-Extended, that is a separate group in the same file, and they write down why, because it does not change whether the standup article can appear in Search. They do not add nosnippet to the article to “save the click.” The article’s job is to be the page someone opens, and a passage someone can quote.
How this shows up when BloGoose publishes
A post BloGoose sends to WordPress or to your API is meant to be a public article. The destination should not wrap it in noindex. After the first publish, view the source of that URL. You want one canonical link, a title, and no content="noindex". A WordPress setting named along the lines of “discourage search engines” adds a sitewide noindex. It is the right switch for a staging host and the wrong switch for the site you are trying to grow. Turn it off on production. Leave it on for the staging copy, and keep staging from being linked as if it were the real site.
Submitting the URL to the Indexing API does not override noindex. If the page says noindex, asking Google to visit only helps Google see the noindex sooner. Fix the tag, then worry about discovery. The sitemap should list the article and should not list the thank-you page. Which URLs belong in that file is the XML sitemap guide. Leaving a URL out of the file is not the same as noindex.
BloGoose does not need a special AI meta tag on each article to be quotable. It needs the article to be crawlable, indexable, and written so the answer is in the HTML. Snippet controls and Google-Extended are site decisions. Make them on purpose, once, and do not let a plugin make them on every post.
Questions about robots meta tags
What is a robots meta tag?
A robots meta tag is an HTML element that tells crawlers how a single page may be indexed and shown. The common value is noindex, which asks Google not to show that URL in search results. Google can only follow the tag if it is allowed to crawl the page.
What is the difference between noindex and robots.txt?
noindex is an instruction on a page Google has crawled: do not show this URL in results. A robots.txt disallow tells Google not to crawl the URL. A disallowed URL can still appear in results if another site links to it, and Google will not see a noindex on a page it is not allowed to crawl.
Should you noindex a blog post with no traffic?
No. Low traffic is not a reason to hide a page that still answers a question. Use the content audit labels for that decision: keep, update, merge, or leave. noindex is for a URL that should not be a search result, such as a thank-you page, an internal search page, or a draft preview.
Does nosnippet block AI Overviews?
Google’s robots meta documentation, updated 24 March 2026, says nosnippet applies to AI Overviews and AI Mode, and prevents the page from being used as a direct input for those features. It also removes the text snippet in regular results. Do not put nosnippet on an article you want quoted.
Is Google-Extended the same as noindex?
No. Google-Extended is a robots.txt token, not a robots meta tag. It controls whether content Google crawls may be used to train future Gemini models and for some grounding. Google says it does not affect inclusion in Google Search and is not a ranking signal. Blocking Googlebot is a different decision, and it can remove the site from Search.
What if a plugin adds noindex by accident?
The article will drop out of results after Google recrawls it, even if the page is useful. View the source of one live post and look for a robots meta tag. A published article should not contain noindex. A sitewide discourage-search-engines setting is the same mistake at a larger scale.
Publish the article without noindex, and keep robots.txt from blocking it.
Start the 1-day trial