A canonical tag is how you name the address you want when one page can be opened at more than one URL. Duplicate content, for this decision, is that situation: the same document, or a very similar one, available more than once. It is not two articles that happen to share a topic. Google’s page on how to specify a canonical URL, updated 10 July 2026, calls the tag a strong hint. A redirect is stronger. A sitemap listing is weaker. None of the three is a command, and a site can do fine if you never set a preference, because Google will pick a URL on its own.
Choose one URL. If the other address should disappear, redirect it. If both addresses need to stay up, put a canonical tag on each, including the preferred page, pointing at the URL you want in search results. Use an absolute URL in the head. Do not point a distinct article at a different article. That is a merge, which belongs in an SEO content audit, not in a tag.
What is a canonical tag?
Canonicalization is the process of selecting the representative URL of a piece of content. The canonical URL is the address Google chose as the most representative from a set of duplicate or very similar pages. A search result usually points at that URL. The duplicates are crawled less often, which is Google’s way of spending less time on copies.
A canonical tag is the HTML way to state your preference. It is a link element with rel="canonical" in the head of the page. The href is the URL you prefer. Google also accepts the same hint as an HTTP Link header, which matters for a PDF or another non-HTML file. Pick one of those two methods. Sending one URL in the header and a different URL in the element is an easy way to contradict yourself.
The element is only accepted in the head, and the head has to be valid HTML. A tag pasted into the article body is ignored. Google recommends an absolute URL, such as https://example.com/async-standups, rather than a path that starts with a slash. Relative paths are supported and still cause trouble, including when a staging host is crawled and the relative tag resolves to the staging host.
Put the same self-referencing tag on the preferred page. The preferred page then agrees with the copies. That agreement is the point. A self-referencing tag on a site that never had a second URL is consistency, not a ranking trick. Google says specifying a preference is generally not critical. You add it when more than one address can show the page, or when you want the signals those addresses collect to land on one URL.
Google lists four reasons to bother. You want people to see a particular URL in results, such as the clean article rather than the same article with a campaign parameter. You want links and other signals that point at the copies to consolidate on the preferred URL. You want one set of metrics for one document. You would rather Googlebot spend time on new or updated pages than on copies. Those are the reasons. “Add a canonical tag so the page ranks” is not one of them.
What duplicate content means here
Google clusters pages when the primary content looks the same or very similar, then marks one URL in the cluster as canonical. Exact copies are the obvious case: the article at /async-standups and the same HTML at /async-standups?utm_source=newsletter. Very similar pages count too, such as a print stylesheet URL that renders the same article without the navigation.
Two articles that answer different questions are not that cluster, even when they mention the same product. A procedure for running an async standup and a comparison of Scrum and Kanban for six people can link to each other. Each one keeps its own canonical URL, which is itself. Pointing the comparison at the procedure would ask Google to treat a different document as a copy. If the pages really do the same job, the editorial decision is a merge: keep one URL, redirect the other, and say so in the content audit. The tag is the wrong tool for a page you wish were the other page.
A trailing slash, a www host, an HTTP URL, and an uppercase path can all be the same document if the server returns the same page for each. Pick one form and send the others to it with a redirect when you can. The same WebSite name belongs on each of those home-page copies, which is the site names guide. Hyphens, parameters, and that single case are the URL structure guide. If a system you do not control keeps emitting the extra form, the tag is the fallback. Google prefers HTTPS over HTTP for equivalent pages, unless the certificate is invalid, the HTTPS page pulls in insecure dependencies other than images, the HTTPS page redirects through HTTP, or the canonical tag on the HTTPS page points at the HTTP page. Do not put the HTTP URL in the sitemap if the HTTPS URL is the one you want.
Canonical tag or redirect
The practical split is whether a person should still land on the extra address.
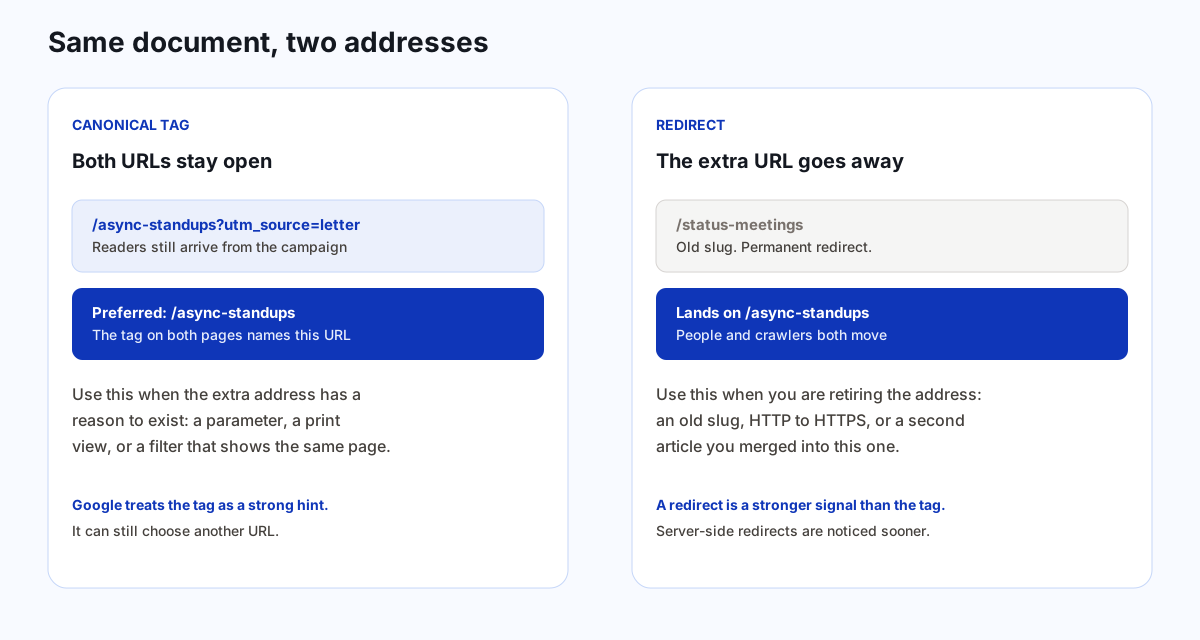
Use a permanent redirect when you are deprecating the duplicate. An old slug that promised the wrong document, an HTTP address after you moved the site to HTTPS, or a second article you consolidated into one URL all belong here. People who bookmarked the old address, and crawlers that still know it, land on the page you kept. Google says every permanent redirect method has the same effect, and a server-side HTTP redirect is noticed sooner than a slower alternative. The status-code choice, a 301 or 308 versus a 302, plus meta refresh and a JavaScript hop, is the redirects guide. The content refresh guide covers the editorial half of a slug change: change the address only when the old slug lies, then redirect. If nothing replaced the page, do not send that URL to the homepage. Return a 404. A 200 that only says the page is missing is a soft 404. A long chain of redirects is a separate crawling cost on a very large site, which is the crawl budget note. One hop to the page you kept is the pattern here.
Use a canonical tag when the extra address has a reason to keep returning the page. A tracking parameter has to stay on the URL or the campaign report breaks. A print view is there because someone asked to print. A filter that does not change the main content is the same article with a query string. A canonical is the hint when that filtered URL stays a 200. The faceted navigation guide is why that hint is a weaker crawl control than not generating the URL. In each case both URLs return 200, and each head points at the clean URL. The person stays where they are. Search is asked to show the clean one.
Do not stack the two in a confusing way. A redirect already tells Google the target is preferred. Adding a canonical tag on the target that points back at the URL you just redirected undoes the move. After a redirect, internal links should use the target as well, so you are not sending people through a hop you already decided to remove.
How strong each signal is
Google orders the methods by how strongly they can influence the choice. Redirects first. Then rel="canonical" annotations. Then inclusion in a sitemap, which is a weak signal. Using two or more, aimed at the same URL, raises the chance that your preference is the one that appears. Aimed at different URLs, they cancel the clarity you were trying to add.

| Situation | What to do | What to leave alone |
|---|---|---|
| Old slug, HTTP host, or a merged article | Permanent redirect to the URL you keep | A canonical tag that points back at the old address |
| Tracking parameter, print view, or a filter with the same main content | Canonical tag on every copy, plus a self-reference on the preferred URL | A redirect that would break the parameter or the print view |
| The one URL you want crawled as the article | List it in the sitemap and link to it from other pages | Also listing the parameterized copy |
| Two articles with two jobs | Each page canonicals to itself | A tag from the weaker article to the stronger one |
Google also prefers the HTTPS version of an equivalent page, and it prefers URLs that participate in an hreflang cluster over a near-duplicate that the cluster never mentions. If you publish the same article in two languages, the canonical should be a page in that language, or the closest substitute if a same-language canonical does not exist. A tag that points the German article at the English article throws away the language signal. Annotations that combine rel="canonical" with hreflang, lang, media, or type are not used for canonicalization. Language alternates belong on rel="alternate". The hreflang guide is the return links, the language codes, and the rule that each translated URL lists itself.
When a blog actually needs one
Most articles on a small site have one address. The tag you need is the self-reference, if your templates emit one, and a redirect for the host variants: HTTP to HTTPS, and www to the host you chose, or the reverse. Do that once at the server. Doing it inside every article is how the hints drift.
Look for a second address when a tool appends one. Email platforms add utm_ parameters. Some themes offer a ?replytocom= URL or a print path. A staging plugin can leave a public preview URL that returns the same HTML. A tag archive and a category archive that list the same posts are a different problem: those pages are not copies of an article, and canonicalizing an archive to a post hides the archive for the wrong reason. Decide whether the archive is a page you want in search. If it is only a duplicate list of the same posts with no introduction of its own, a cleaner fix is to stop indexing that archive, or to give it a real job. Google does not recommend noindex as the way to pick a canonical inside one site, because noindex blocks the URL from Search entirely. Use noindex only when you truly do not want that URL as a result.
WordPress and other CMS tools often write the canonical element for you. That is useful until a theme and an SEO plugin both write one. View the source and count the rel="canonical" elements. One is enough. Two, with different href values, is the conflicting-signal case Google tells you to avoid. The same check applies if JavaScript injects a second tag after the HTML already set one. Google’s advice is to put the canonical URL in the HTML source and not let JavaScript change that element. If you cannot put it in the source, leave it out of the source and set it only with JavaScript. Two writers is the failure mode. The JavaScript SEO guide is the rest of that limit: a script must not change the canonical to a different URL, and a noindex tag in the HTML can skip rendering entirely.
Moves that fight the hint
A few popular fixes are listed by Google as practices to avoid, because they do something harsher than picking a URL.
- robots.txt is not a canonical signal. A disallowed URL can still be indexed without its content, from links elsewhere. Blocking the copy does not tell Google which URL you prefer, and it can prevent Google from seeing that the copy is a copy.
- The URL removal tool hides URLs. It is not a way to nominate a preferred address. Removing a URL removes it from results, which is the wrong outcome when you only wanted the clean URL to be the one that shows.
- Do not canonical a fragment. Google generally does not support a URL fragment, the part after
#, as a canonical. The preference is a full URL of a document, not a heading halfway down the page. - Do not mix methods. The sitemap, the tag, the redirect, and the internal links should name the same preferred URL. One URL in the sitemap and a different URL in the tag is an explicit contradiction.
- Do not canonical across different jobs. A stronger article does not become the canonical of a weaker, different article because you hope the links will pool. Signals consolidate for similar or duplicate pages. A topic cluster keeps those jobs on separate URLs and links them in sentences.
- Do not noindex the URL you hope will win. If the preferred page is noindex, it cannot be the result. The tag was supposed to point at a page Google is allowed to show. noindex is for a URL that should not be a result at all.
There is also a quiet failure when the preferred URL redirects, 404s, or points its own canonical somewhere else. The hint then asks Google to prefer an address that does not stand on its own. Open the href in a browser. It should be the page you would send a reader, with a 200 response, and its own tag should point at itself.
Sitemap and internal links
A sitemap that lists only preferred URLs is a weak canonical signal and a useful maintenance habit. The XML sitemap is that file: which URLs to list, and what lastmod may say. Google still has to decide which other URLs are the duplicates. Listing both the clean article and the parameterized copy suggests both are canonical, which is the opposite of what you want. After you redirect an old slug, take the old path out of the sitemap. The redirect is the signal. The sitemap should not keep nominating the address you retired.
Internal links do as much as the tag on a site you control. Google’s best-practice list says to link to the canonical URL rather than a duplicate. If the navigation, the breadcrumb, the related-article block, and the body links still use ?utm_source=internal or the old slug, you are voting against the tag with the links people actually follow. Pick the clean URL in the template once. Campaign parameters belong on links you give to other sites, not on every link inside your own.
When you cite another document, the link should be that document’s preferred URL too. Sending a reader to a parameterized copy or an old slug makes their browser do extra work and teaches your own site the wrong address. The citing sources guide is about which document to name. This one is about which of your addresses represents the page.
When Google picks a different URL
Search Console is where you see Google’s choice. In the page indexing report, a URL can be grouped as a duplicate even when you set a tag. “Duplicate, Google chose different canonical than user” means Google saw your hint and selected another URL. “Duplicate without user-selected canonical” means Google saw copies and you did not state a preference. “Alternate page with proper canonical tag” is the copy behaving as a copy: it is not a failure.
If Google’s choice surprises you, compare the two URLs as Google would. Is the main content actually the same? Does the tag sit in the head, once, with an absolute HTTPS URL that returns 200? Does the sitemap list the other one? Do your templates link to the other one? Does the page you want carry a noindex, or a canonical that points elsewhere? A mobile URL on a separate host can be chosen for a mobile searcher even when the desktop URL is your canonical. That exception is in Google’s canonicalization notes. It is not a reason to add a second tag.
Fix the disagreement, then wait for a recrawl. Changing the tag hourly does not create a new vote. The page indexing status is a check that the hint landed, the same way the audit uses index coverage after a merge. It is not a scoreboard.
A canonical URL example
Northwind’s procedure lives at https://northwind.example/async-standups. The newsletter tool rewrites shared links to /async-standups?utm_source=newsletter. A print stylesheet is available at /async-standups/print because the office posts the agenda on a wall. An older URL, /status-meetings, was the same procedure under a slug that now sounds like a different meeting.
The preferred URL is /async-standups. It carries a self-referencing canonical tag, it is the only one of the four in the sitemap, and every internal link uses it. The newsletter URL and the print URL return 200 and each canonical tag points at /async-standups. People coming from the email keep the parameter so the campaign can be counted. People who open the print view still get the print view. /status-meetings returns a permanent redirect to /async-standups, because that address should not remain a second copy, and the refresh already decided the slug was wrong.
What Northwind does not do: it does not canonical the Scrum-versus-Kanban article to the standup procedure, even though the comparison links to the procedure and ranks for fewer queries. Those are two jobs. It does not add the newsletter URL to the sitemap “so the campaign is indexed.” It does not disallow /print in robots.txt and hope that counts as a preference.
How this shows up when BloGoose publishes
When BloGoose sends an article to WordPress or to your API, the canonical URL is the address of that post: your site, plus the slug you approved. If the draft metadata leaves the field empty, BloGoose derives it from the site URL and the slug. It does not invent a second URL to match a keyword, and it does not point the new article at an older one.
You still own the host-level redirects. HTTP to HTTPS, and the choice between www and the bare host, are server settings, not fields on one article. If a plugin on the destination site writes a different canonical than the one BloGoose sent, the published source will contain two hints. Check one live article after the first push: one canonical element, absolute, HTTPS, matching the URL in the address bar and the URL in your sitemap.
A later refresh keeps that same canonical. The update changes the passage, the visible date, and dateModified together. It does not mint a new address unless the slug itself is misleading, in which case the old address redirects and the new address becomes the only canonical.
Questions about canonical tags
What is a canonical tag?
A canonical tag is a link element in the head of a page that names the URL you prefer when the same or very similar content is available at more than one address. Google treats it as a strong hint. Google can still choose a different URL.
What is duplicate content?
Duplicate content, for this decision, means one document available at two or more URLs, or pages whose main content is very similar. Two articles that answer different questions are not duplicates, even if they share a topic.
Should you use a canonical tag or a redirect?
Use a redirect when the extra URL should stop existing, such as an old slug or an HTTP address you are retiring. Use a canonical tag when both addresses need to stay available, such as a tracking parameter or a print view, and you still want one URL in search results.
Can you canonical one article to a different article?
Only when the pages are duplicates or very similar. Pointing a distinct article at a stronger, different article is not how canonicalization works. If two articles compete for the same job, merge them and redirect, or keep both and give each its own query.
Does a sitemap replace the canonical tag?
No. Listing the preferred URL in a sitemap is a weak signal. The canonical tag and a redirect are stronger. Use them together, and do not list one URL in the sitemap while the tag names another.
What if Google picks a different canonical?
Google’s choice is allowed. Check that the tag, the sitemap, and your internal links all name the same preferred URL, that the tag is in the head, and that it uses an absolute URL. A noindex on the page you prefer, or a canonical that points at a different document, gives Google a reason to ignore the hint.
Publish the article at one address, and let the canonical field match it.
Start the 1-day trial