Scaled content abuse is when many pages are generated mainly to manipulate search rankings and not to help a reader. AI content is not the definition. Google’s spam policies say the practice is unoriginal pages with little or no value, no matter how they are created. A model can draft a page a person stands behind. A model can also stamp out a hundred pages that only swap a keyword. The second set is the policy. The tool is not.
Judge the set, not the software. One reviewed article that answers a real question can use a model in the draft. A library of near-copies, scraped rewrites, or pages that exist so a query has a URL, should not be published for Search. Google’s instruction if you are hosting that set is to exclude it from Search. Hiding it from people while showing it to crawlers is a different violation.
What scaled content abuse is
Google defines spam, on that same policy page, as techniques meant to deceive users or to manipulate Search systems into featuring content, including attempts to manipulate generative AI responses in Google Search. Scaled content abuse is one of those policies. The useful sentence is the purpose: many pages, primary aim is ranking, users are not helped. Volume alone is not the test. A newsroom publishes many pages. A documentation site publishes many pages. The abuse is unoriginal bulk whose reason for existing is the query, not the reader.
The policy lists examples, and they are examples, not a closed list. Using generative tools to produce many pages without adding value. Scraping feeds, results, or other sites, including automated synonym swaps, translation, or other obfuscation, again without much value. A real translation, connected with return links, is the hreflang case. A translated shell with the same empty body is this policy. Stitching pieces from other pages. Standing up several sites so the scale is harder to see. Publishing many pages that barely make sense to a person but contain the keywords. A human writing the same empty page two hundred times is included. The older idea that “automation” was the whole violation is what this wording replaced. People count. Tools count. The combination counts.
Sites that violate spam policies may rank lower or not appear in results. Google says it detects violations with automated systems and, when needed, human review that can become a manual action. There is no switch in a plugin that certifies a site as safe. There is also no rule that a page is unsafe because a model touched the draft.
What Google said about AI content
On 8 February 2023, Danny Sullivan and Chris Nelson published Google’s guidance on AI-generated content. The post says ranking systems aim to reward original, high-quality content, and that the focus is the quality of the content rather than how it is produced. It says using automation, including AI, to generate content with the primary purpose of manipulating rankings violates spam policies. It also says not all automation is spam. Sports scores, weather, and transcripts were automated long before chatbots. AI can help people make useful pages.
The FAQ on that post is the part worth keeping next to the spam policy. Appropriate use of AI is not against the guidelines. Google does not ban AI content, because automation has long been part of publishing. Using AI gives no special ranking gain. If the page is useful, original, and shows the qualities they describe as experience, expertise, authoritativeness, and trust, it might do well. If it is not, it might not. If you see AI as a cheap way to game rankings, the post’s answer is not to use it that way. If you see it as help producing something helpful and original, it might be worth using.
That post points publishers at the helpful-content guidance and at three questions: who made the page, how it was made, and why. Why is the scaled-content question. “To have a URL for every related query” is a why that matches the policy. “To explain the procedure our team actually uses” is a why that matches a normal article. Who and how still matter. A reader who would ask who wrote this should see a real byline. A reader who would ask how it was made should see a disclosure when that expectation is reasonable. The author page guide is those choices. Listing the model as the author is the choice Google’s FAQ advises against.
Patterns the policy names
You can recognize the set without a ranking report.
| What you published | Why it fails the policy | What a real page does instead |
|---|---|---|
| The same guide with a city, a year, or a tool name swapped | The set is there to match queries. The reader in that city learns nothing local. | One page about the procedure. Mention a place only when you have something true to say about it. |
| A rewrite of the current top results, paragraph for paragraph | Little is added. Scraping and light rewriting are named patterns. | Cite the primary document and add the explanation only you can give. Citing sources is the sentence, not a license to copy. |
| Pages that are mostly keywords and barely readable | The policy names pages that make little sense to a reader but contain the queries. | A title and a body a person can finish. Stuffing is its own spam policy too. |
| Several domains publishing the same library | The policy names multiple sites used to hide the scale. | One site, with a cluster of pages that are actually different. |
A content calendar of eight guides, each with its own question, is not this table. A content calendar of two hundred URLs generated from a column of modifiers is this table, even if each URL had a “brief” that only changed the modifier. The content brief is a defense when it forces a scope, sources, and a stop. It is not a defense when it is a mail-merge.
Policies people mix up with it
Neighboring rules are not synonyms. Treating them as one “AI penalty” makes the fix nonsense.
- Site reputation abuse is third-party content placed on a host mainly to use that host’s ranking signals. Freelance pages, white-label sections, and partner content can qualify when the reason they live on the host is the host’s reputation. Your own product guides are not this. A payday-loan section on an education site, which readers would not expect, is the kind of example Google gives. Google’s August 2026 update says that from 30 August 2026 a manual action under this policy affects results differently for searchers in the European Economic Area than outside it. That regional note is about this policy, not about every article a model drafted.
- Expired domain abuse is buying a lapsed domain and filling it with low-value content to use whatever reputation the old site had. It is not “we have published for a year.”
- Doorway abuse is pages or sites built to rank for similar queries and then pass people to somewhere else. City pages that funnel every visitor to one signup are the usual shape. They often travel with scaled content. They are still a separate line in the policy.
- Scraping is republishing someone else’s content, including a light synonym edit, to manipulate rankings. A citation is not scraping. A page that is the other page with the nouns changed can be.
- Thin affiliation is product pages copied from merchants, or the same affiliate template repeated, without a review, a comparison, or another reason to exist. Affiliate links are allowed. A network of copies is the problem.
Cloaking and sneaky redirects are how some of these sets are hidden: people see one thing, crawlers see another, or everyone is bounced to a page they did not ask for. Do not “fix” a scaled set by showing Google a different article than you show a reader. Google’s remedy for hosting scaled content abuse is to exclude it from Search.
The purpose test

Read five URLs from the set, not the prompt. Could a person who has the problem finish one page and do the thing? Did any sentence require knowledge that was not already on the pages you asked the model to imitate? Is the byline someone, or some organization, who can correct an error? If you removed the target keyword, would the page still have a reason to be on the site? Those are editorial questions. They are also the practical reading of “little or no value” and “not helping users.” The wider self-check, including who the page is for when search is not the reason it exists, is the helpful content guide.
Original does not mean “a statistic you invented so the page looks researched.” An invented number is a false page, whether a person or a model typed it. Original means you added something you can stand behind: the steps your team uses, the constraint your product actually has, the document you cited, the mistake you will correct. The content audit is how you label URLs that never had that. Keep, update, merge, or leave. A leave that should not be a result is not a prompt to generate a replacement in the same shape.
If those pages are already live
Google’s line is short: if you are hosting this content, exclude it from Search. For a URL that should stop being a result, that means a real removal: delete it and return 404 when nothing replaces it, redirect it when another URL truly does, or noindex it when the URL must remain for people and must not be a result. The robots meta page is noindex. Do not disallow the URLs in robots.txt and call that exclusion. Google cannot see a noindex on a URL it is not allowed to crawl, and a blocked URL can stay indexed from other links.
Do not noindex the guides you want found because they share a template with the bad set. Split them. The city pages go. The standup procedure stays, if it is actually a procedure. Then take the bad URLs out of the sitemap. Leaving them listed asks for a crawl of pages you are trying to drop.
A manual action, if one is applied, shows in Search Console for the registered owner. The policy page is the reference for what to change before a reconsideration request. Rewriting the same pages with a different model is not a change of purpose. Neither is adding a FAQ, a star rating, or a fake author so the URL looks more like a guide.
Bylines, disclosure, and citations
Google’s 2023 FAQ says to consider an accurate byline where a reader would ask who wrote this, and a disclosure where a reader would ask how it was made. It says giving the AI itself the byline is probably not the way to disclose that a model was involved. Say the organization, or the person who reviewed it, and say that a model drafted a section if that is something a reader of this page would need to know. Do not invent a person so the set looks expert. An invented expert on two hundred pages is the policy plus a trust problem.
Citations do not launder a copied page. Name the document you used, in the sentence that depends on it. If the page has nothing to add after the citation, it did not need to be a separate URL. Schema should describe the page you showed, which is the article schema rule. Markup does not turn a scaled set into a set of articles.
Search results and AI answers
The spam-policy introduction covers generative AI responses in Google Search, not only the blue links. Publishing a pile of near-copies so an answer engine has more passages to quote is the same purpose problem. Answer engines quote text. They can quote a thin page if that is the text they fetched. The way through is a passage that is true and specific, on a URL that deserves to be fetched. It is not a hundred openings that repeat the definition with a different city.
A disclosure in the footer of every page, and no original explanation in the body, does not make the passage quotable. The answer engine guide is about the passage. This page is about not manufacturing passages whose only job is to be selected.
A scaled-content example
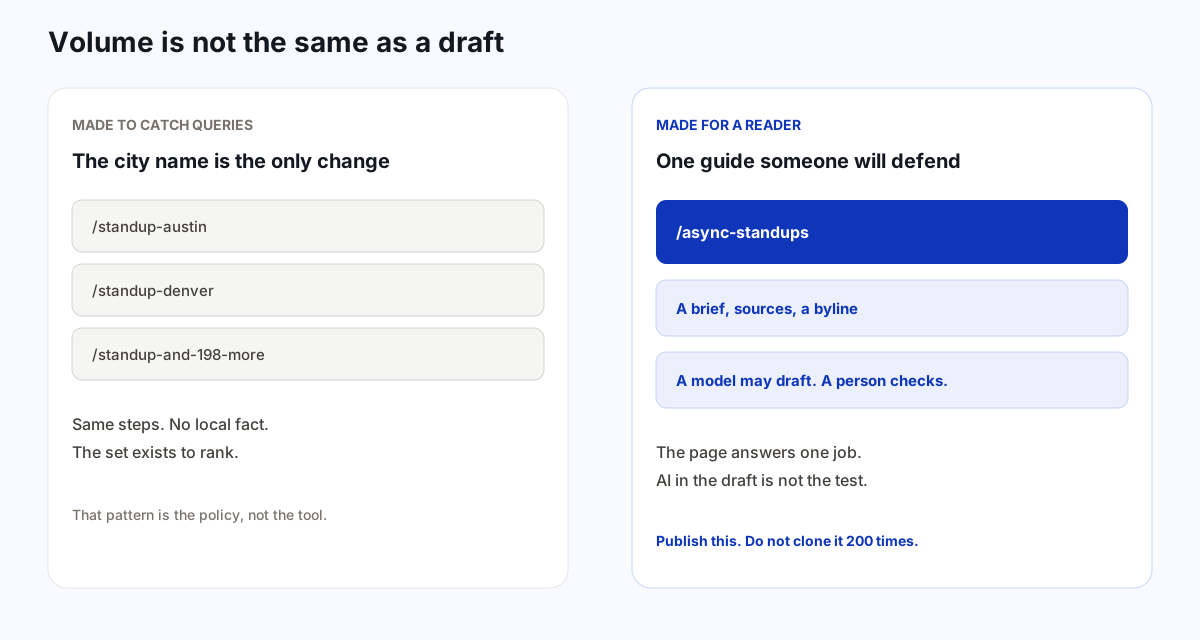
Northwind’s useful URL is /async-standups. It explains the cutoff, the three prompts, and what to do when someone misses it. Priya reviews it. The sources are named. A model drafted the first version from the brief and from the product’s actual behavior. That page can stay in Search. Using a model is not the interesting fact about it.
The set that should not ship is /standup-austin, /standup-denver, and the rest of a column of cities. Each page is the same three prompts with the city in the first sentence. Nobody on the team has run the meeting in those cities. The pages exist because a keyword tool listed the modifiers. That is scaled content abuse, and it is close to doorway abuse if every page only funnels to the signup. The fix is not to add “as of 2026” or a stock photo of each skyline. The fix is not to publish them. If they are already live, exclude them: 404 or noindex, and remove them from the sitemap. Keep the one guide.
A second site, bought because an expired domain used to be a school, filled with the same city pages, adds expired-domain abuse to the same library. Do not do that either. One honest site is the whole strategy.
How this shows up in a BloGoose draft
BloGoose drafts from your site, your sitemap, and a brief for one article. That is a production choice, not a certificate. You still decide whether the next URL is a new question or a modifier on the last one. If the calendar proposes a page that only changes a place, a year, or a synonym, reject it. If a draft repeats a page you already have, refresh that URL or drop the draft. The pipeline is the machinery. This policy is the reason not to point the machinery at a keyword grid.
Review is the line. A person or the organization should be able to correct a step, point at the source, and explain why this URL is not the next URL. When that review is real, a model in the draft is compatible with Google’s 2023 guidance. When the review is a click on publish across a folder of copies, the policy does not care which model wrote them.
Questions about scaled content abuse
What is scaled content abuse?
Scaled content abuse is when many pages are created mainly to manipulate search rankings rather than to help a reader. Google’s spam policies say this applies no matter how the pages are produced. Generative tools, scraped text, and stitched pages can all qualify when they add little value.
Is AI content against Google’s guidelines?
No. Google’s February 2023 guidance says appropriate use of AI or automation is not against its guidelines. Using automation, including AI, mainly to manipulate rankings is a spam-policy violation. The test is the purpose and the value of the page, not the tool.
Does using AI help a page rank?
No. Google says using AI does not give content any special gain. If the page is useful, original, and trustworthy, it might do well. If it is not, it might not. A disclosure or a schema type does not change that.
What is the difference between scaled content abuse and site reputation abuse?
Scaled content abuse is a volume of unhelpful pages, including on your own site. Site reputation abuse is third-party content placed on a host mainly to borrow that host’s ranking signals. Publishing your own product guides is not site reputation abuse. Hosting someone else’s unrelated offers so they rank on your domain can be.
Should you noindex every AI-written draft?
No. noindex is for a URL that should not be a search result. A reviewed article that answers a real question should stay indexable. noindex the pages that exist only to catch queries, or remove them. Do not hide the pages you actually want found.
Can a content brief prevent scaled content abuse?
A brief makes one page accountable: one query, one reader, sources, and a person or organization who will stand behind it. It does not bless a plan to publish hundreds of near-copies. If the plan is a page for every city, with the city name swapped, the brief is being used as a template for the policy, not as a defense against it.
Draft the page a reader needed. Leave the keyword grid unpublished.
Start the 1-day trial