JavaScript SEO is the work of making a page discoverable when scripts build or change it. Rendered HTML is the DOM after those scripts run. Google’s JavaScript SEO basics, updated 4 March 2026, say Google Search runs JavaScript with an evergreen version of Chromium. The same page says server-side or pre-rendering is still a good idea, because it is faster for people and for crawlers, and because not every bot can run JavaScript.
Put the article, the title, the links, and the canonical URL in the HTML you send. Google may render the script later. An answer engine, or any crawler that does not execute JavaScript, will not. An empty app shell is a container. It is not the page.
What JavaScript SEO is
Two old stories are still in circulation. One says Google cannot execute JavaScript, so a script-built page is invisible. The other says rendering solved it, so an application can ship an empty document and fill the article in the browser. The current documentation is between them. Google can run JavaScript. It does that in a later step, with limits, and it still recommends that the response already contain the content.
That matters more for a blog post than for a logged-in dashboard. A dashboard can require an account. A guide is supposed to be found. If the only copy of the steps exists after a bundle downloads, parses, and paints, every system that reads the first response gets a headline and a loading spinner. People on a slow phone wait. Crawlers that do not run scripts never see the steps. Google may see them after rendering, and it may not, if the render is skipped or the script fails.
JavaScript is still a normal part of a page. A small script for a menu, a comment form, or a chart does not make the article ineligible. The failure is when the script is the article. Navigation, the H1, the paragraphs, and the links to the next guide should be in the response even if JavaScript never runs. Enhance the page after that. Do not withhold it.
Crawl, then render, then index
Google describes three phases: crawling, rendering, and indexing. They are not one instant.
Googlebot keeps a queue for crawling and a queue for rendering. It is not obvious from the outside which queue a URL is in. When it fetches a URL, it checks robots.txt first. A disallowed URL is not requested, and JavaScript on that URL is not run. Google Search will not render JavaScript from blocked files or on blocked pages. If the article’s script, or the CSS it needs, is disallowed, the rendered page can be the broken version. Allow the resources the page needs to display. The robots meta page is the separate question of noindex. Blocking the article in robots.txt is not how you hide it, and it is also not how you help a script-built page.
After a successful fetch, Googlebot parses the HTML response for URLs in the href of links and adds those URLs to the crawl queue. Links injected into the DOM by JavaScript can be found too, if they are real anchors with an href. That discovery often waits until rendering. The first wave only sees what the response already contained. A pagination control that is a button, or a “next” link that a script writes later, is missing from that first wave.
Pages that return HTTP 200 go to the rendering queue, unless a robots meta tag or header says not to index them. The wait can be a few seconds. It can be longer. When resources allow, a headless Chromium renders the page and runs the JavaScript. Googlebot parses the rendered HTML for links again, and Google uses that rendered HTML to index the page. Non-200 responses, such as a real 404, may skip rendering.
Every 200 page is sent toward rendering, whether or not it uses JavaScript. Rendering is not a prize you unlock by adding a framework. It is a second pass Google may spend on the URL. Time spent rendering counts as crawl time, which is why the crawl budget guide treats a heavy render as a cost on a large site. On a blog, the cost that matters first is the reader waiting on a bundle before the first sentence.
The HTML response
Classical pages and server-rendered pages put the content in the HTTP response. Google says crawling and parsing that HTML works well. Some JavaScript sites use an app shell: the first HTML is a frame, and the article appears only after a script runs. Google can often still index that article after rendering. The page is slower, the links are late, and any bot that does not execute JavaScript indexes the shell.
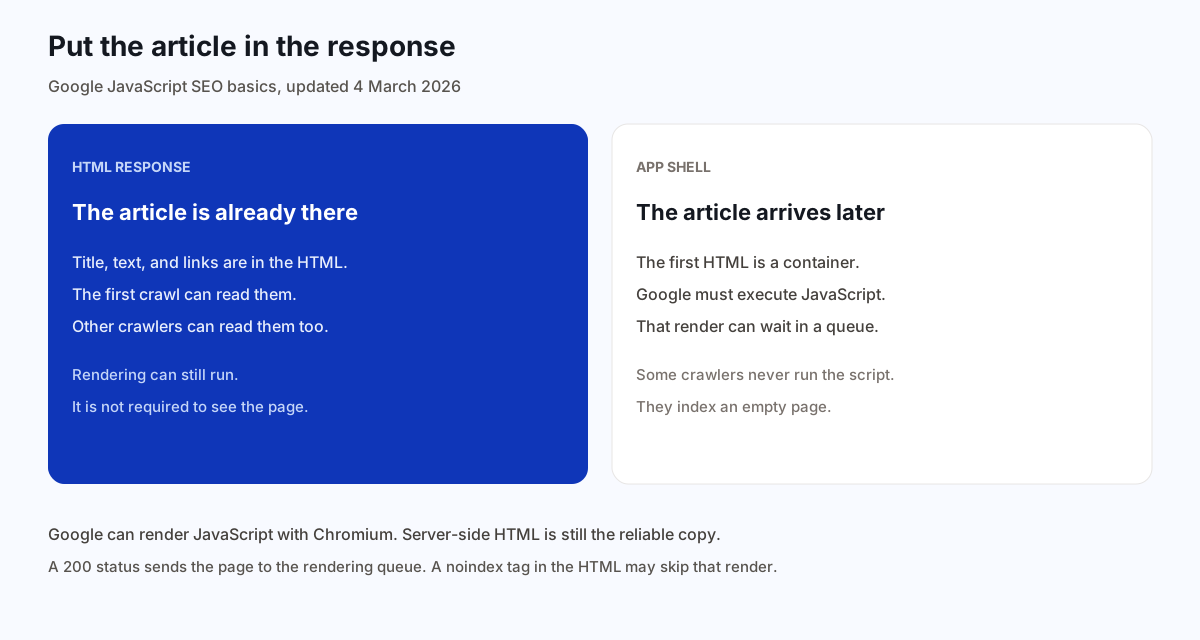
Check this without a tool that runs scripts. View the page source, not the inspector panel after the app has booted. Search for a sentence from the second paragraph. If it is absent, the article is client-rendered. Search for the URL of a related guide. If that href is absent, the link is client-rendered too. The inspector showing the sentence proves the script works in your browser. It does not prove the response contained it.
Server-side rendering and pre-rendering both aim at the same outcome: the response includes the article. Google calls that a good idea for speed and for bots that cannot run JavaScript. Serving one HTML document to Googlebot and a different document to people is not that technique. That split is cloaking when it is used to show a crawler something the visitor does not get. Render the same article for both. The script can then hydrate the page, attach a menu, or load a comment thread. Hydration should not delete the article and fetch a second version that the first crawl never saw.
Answer engines quote text they can extract. A passage inside a bundle is a poor citation. The answer engine guide is about writing a passage that stands alone. This page is about that passage being in the HTML, so the engine does not have to execute a build artifact to find it. JSON-LD can repeat the headline and the author. It is not a second copy of the article hidden from the reader. The article schema guide says to put that block in the response as well. A script may inject JSON-LD, and Google says to test that implementation. Prefer the block in the HTML so a failed script does not take the markup with it.
Titles and the canonical URL
You can use JavaScript to set or change the title element and the meta description. You should not need to. The title tag is the promise of the page, and it should already be in the head of the response. A script that replaces “How to run an async standup” with a different headline after load gives Google two candidates and gives a non-rendering crawler only the first, or only an empty title if the response omitted it. One title, in the HTML, matching the H1, is the stable version.
The canonical URL has a stricter rule. Google says you can set rel="canonical" with JavaScript, and that you should not use JavaScript to change it to a different URL from the one in the original HTML. The best place is the HTML. If you cannot put it there, leave it out of the HTML and set it only with JavaScript. If the HTML already has one, a script must not add a second with a different href, and it must not rewrite the existing one. Multiple or conflicting canonicals can produce unexpected results. The canonical tag page is which URL that single tag should name. This page is only about not letting a script argue with the response.
A common bug is a template that emits the canonical for the HTML file, then a router that “corrects” it to the in-app path after the view loads. View source shows one URL. The rendered DOM shows another. Pick the public URL, write it in the response, and make the router agree. Campaign parameters do not belong in that tag. The clean URL does.
noindex can skip the render
A robots meta tag can keep a page out of the index, or ask Google not to follow its links. You can add or change that tag with JavaScript. There is a trap in the other direction. When Google sees noindex, it may skip rendering and JavaScript execution. A script that removes noindex, or changes it to allow indexing, may never run. If you want the page indexed, do not put noindex in the original HTML.
That is the opposite of a pattern some staging setups use: ship noindex in the HTML “for safety,” then let the production script delete it. The production script is exactly what Google may skip. The live article stays out of the index, or it waits on a render that the tag itself discouraged. Put noindex only on URLs that should stay out, such as a preview token, and leave it out of the public article. The robots meta guide is that choice. Do not use a script as the undo button.
The same caution applies to data-nosnippet toggled on existing nodes. Extraction can happen before or after rendering, so a script is a poor way to reveal or hide a passage. If the passage should be quoted, leave it in the HTML without that attribute.
Real URLs, not fragments
Google can discover a link when it is an a element with an href. For an application that changes views without a full page load, use the History API so each view has a real path. Do not load different page content from a fragment. A link to #/products is a bad pattern in Google’s documentation, because Googlebot cannot reliably resolve it. The fragment is not a separate request. A hash used only so a filter never becomes its own URL is the faceted navigation case, and it does not create a page you can index. A hash-change listener that swaps the contents is invisible to the first parse, and it is an unreliable URL even after rendering.
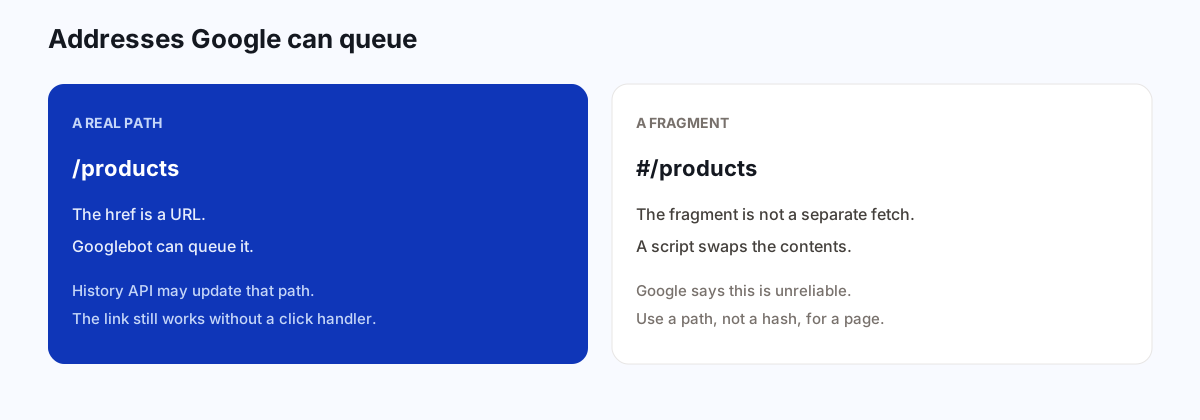
If you intercept clicks to avoid a full reload, the href must still be the real URL. Prevent the browser from navigating, update the history, and swap the view. A visitor with JavaScript disabled, and a crawler reading the response, can still follow the link. A click handler on a div, with no href, has nothing to follow. The pagination guide makes the same point for “load more.” This page adds the routing case: #/guide is not a second article, and /guide is.
Each of those paths should return the relevant HTML if it is requested directly. A server that returns the same empty shell for every path, and relies on the fragment or the router to choose the article, is the app-shell problem again. Direct requests for /async-standups should already contain that article. Client-side routing is an enhancement for people who click inside the app. It is not a substitute for a URL that works on its own. How that path should be spelled, with hyphens and without needless parameters, is the URL structure guide.
Status codes in a single-page app
Googlebot uses HTTP status codes to tell whether the fetch worked, whether the page moved, and whether it should be indexed. Use 404 when the page is gone, 401 when it is behind a login, and a redirect when it has a new URL. A server-side permanent redirect is the one to use for that move. A JavaScript location change is the last resort, which is the redirects guide. A client-side router often cannot do that, because every path returns 200 and the script decides what to paint. That is how a missing article becomes a soft 404: the server said success, and the screen said not found.
Google documents two workarounds when the server cannot send the right code. Redirect with JavaScript to a URL that really returns 404, such as a /not-found path the server owns. Or add a noindex robots meta tag with JavaScript, in the case where the original HTML did not already have one. The redirect is the cleaner match to the soft-404 rule, because the URL Google ends on has a real 404. The noindex approach leaves the missing URL on a 200 until rendering happens, and it fails if you also put noindex in the original HTML of pages you do want indexed. Do not paint “this product is gone” on a 200 and call the router finished.
A deleted blog post should not depend on that workaround. The server can return 404 for an unknown slug without a framework. Reserve the JavaScript strategies for an application whose host really does return one HTML file for every path. Even then, prefer a server rule for unknown paths. The script is the fallback, not the design.
What the rendered HTML must contain
Google supports web components. When it renders a page, it flattens the shadow DOM and the light DOM. It can index only content that is visible in the rendered HTML. If the text never appears there, it will not be indexed. A slot is one way to project light-DOM content into the shadow tree so both show up after rendering. Check with the URL Inspection tool or the Rich Results Test and read the rendered HTML, not only the component source. “Hello” inside a closed shadow root that never gets slotted or copied into the rendered output is content Google says it cannot see.
Structured data can be generated with JavaScript and injected as JSON-LD. Test it. Confirm the rendered HTML contains one block that matches the visible headline, author, and dates. A second block injected by a tag manager, with a different headline, is the conflict the article-schema page already warns about. One block, in the response, removes the test.
Images and other lazy-loaded content need the search-friendly pattern in Google’s lazy-loading guidance. A picture below the fold can wait. The article text should not. The image SEO page covers width, height, and not lazy-loading the first screen. A gallery that fetches the next paragraph only when a person scrolls is the same gap as infinite scroll: the paragraph is not in the response, and the action that reveals it may never run during a crawl.
Googlebot caches aggressively. The web rendering service may ignore caching headers and reuse an old JavaScript or CSS file. Content fingerprinting avoids that by putting a hash of the file in the filename, so a changed file is a new URL. main.2bb85551.js is the pattern Google shows. A bundle named app.js forever, while you deploy new code under that same name, can leave rendering on a stale file. Readers can hit the same bug. The filename is the fix, not a header you hope the renderer honors.
Write script that stays inside what Google’s Chromium can run. Differential serving and polyfills are what Google recommends when you feature-detect a missing API. Some features cannot be polyfilled. If the article’s text depends on an API that fails in the renderer, the article disappears even though your laptop shows it. Keep the text in HTML and the optional API in the enhancement.
A JavaScript SEO example
Northwind’s standup guide is a document, not an application route. The response for /async-standups includes the title, the H1, the steps, the byline, the canonical link to that exact URL, and the links to the related essays. A short script toggles the table of contents on a narrow screen. With JavaScript disabled, the steps are still in the page and the links still work. View source finds the sentence about the cutoff time. There is one canonical tag. There is no noindex. The URL does not use a hash to choose the article.
A redesign proposed an app shell: every guide URL would return the same skeleton, and a client router would fetch the markdown after load. Paths would look like /#/async-standups. Unknown slugs would stay on 200 and show “not found” inside the shell. The canonical would be written by the router. That design fails the response test, the fragment rule, the status-code rule, and the canonical rule at once. They kept the server-rendered article. The router was not shipped.
They still fingerprint the one script they use, so a new deploy is a new filename. They do not disallow /assets/ in robots.txt. The rendered page and the source page tell the same story. That is the whole JavaScript SEO check for a guide.
How this shows up on a published post
BloGoose publishes HTML. The post on your site should be in the response your theme sends, not injected by a front-end bundle that replaces an empty div. If the theme is a JavaScript application, configure it to server-render the post or to pre-render the known URLs. Confirm with view source before you look at Search Console. A URL Inspection render is useful when you suspect the script throws. It is a late check. The source check is the one that tells you whether anyone besides Google can read the article without executing it.
Do not add a script whose job is to rewrite the title, the canonical, or a noindex tag after publish. Set those in the HTML when you publish. Use JavaScript for behavior the article does not depend on. The page can be interactive. The words have to exist first.
Questions about JavaScript SEO
What is JavaScript SEO?
JavaScript SEO is the work of making a page that uses JavaScript discoverable. Google crawls the HTML, may render the JavaScript later with Chromium, and then indexes the rendered page. The reliable version puts the article in the HTML response.
Can Google run JavaScript?
Yes. Google Search uses an evergreen version of Chromium. Rendering is a separate queue after the crawl, and it can take longer than a few seconds. Not every crawler runs JavaScript, so server-side or pre-rendered HTML is still the safer page.
Should the canonical tag be set with JavaScript?
Put the canonical URL in the HTML. If JavaScript also sets it, it must be the same URL. Do not let a script change the canonical to a different address. If you cannot put it in the HTML, set it only with JavaScript and leave it out of the original HTML.
Can JavaScript remove a noindex tag?
Do not count on it. If the original HTML contains noindex, Google may skip rendering and JavaScript execution, so a script that tries to remove the tag may never run. If you want the page indexed, do not put noindex in the HTML you send.
Are fragment URLs OK for different pages?
No. Google says not to use fragments to load different page content, because it cannot reliably resolve those URLs. Use normal links with an href, and the History API if the app changes the view without a full reload.
What should a single-page app return for a missing page?
Prefer a URL whose server returns 404. Google also documents a JavaScript redirect to such a URL, or adding noindex with JavaScript when the original HTML did not already include a robots meta tag. A 200 page that only says the item is missing is a soft 404 until that fix exists.
Ship the article in the HTML. Let the script improve the page after that.
Start the 1-day trial