A URL structure is the set of addresses on a site, and the rules for how those addresses are built. A descriptive URL uses words a person can read. Google’s URL structure documentation, updated 10 December 2025, says a structure that fails its crawl rules can be crawled inefficiently: far too much, or not in a useful way. The same page asks you to make the structure easy to understand. Those are two jobs. The first is so Googlebot can request the URL. The second is so a person, and Google, can tell what the URL is for.
Give each article one path made of words, separated by hyphens, in one case, with no fragment and no parameter the page does not need. Encode real parameters with an equal sign and an ampersand. Do not mint a new URL for a session, a referral code, or every combination of filters.
What a crawlable URL structure is
Google Search supports URLs as defined by IETF STD 66. Characters that standard reserves have to be percent-encoded. That is the floor. A URL that breaks the standard is not a style problem. It is an address some clients will not request the way you intended. You do not need to memorize the reserved list to publish a blog. You need the addresses you ship to be ordinary URLs: a scheme, a host, a path, and a query only when the query changes what the page is.
The crawl rules on that page are short. Do not use a fragment, the part after a hash, to change the content of the page. Google generally does not support that. When you do use parameters, separate the key and the value with an equal sign, and add the next parameter with an ampersand. Several values for one key can use a character that does not fight the standard, and a comma is the example they give. A colon between the key and the value, or brackets to stack parameters, is the pattern they mark as not recommended. A single comma between keys, and a double comma between pairs, is the same kind of private encoding. Crawlers are good at the common form. They are not obliged to learn your dialect.
Inefficient crawling, in Google’s wording, includes extremely high crawl rates and also failing to crawl. A messy structure can do either. Thousands of filter URLs can absorb fetches. A fragment-only app can leave the article undiscovered. Neither outcome is a ranking bonus for a short slug. The slug is how the page is found and recognized. Canonical tags choose among addresses that already return 200. A redirect retires an address. This page is about the address you create.
Descriptive words
Google recommends organizing URLs so they are logical and intelligible to humans. When you can, use readable words rather than long ID numbers. /async-standups says what the page is. /index.php?topic=42&area=3a5ebc944f41daa6f849f730f1 says that a database has a row. Both can be crawled. Only one helps a person decide the link is the standup guide before they open it. The same clarity helps Google associate the URL with the topic of the page. That is not a promise that the words in the path outrank the words in the article. The article still has to be the article. A perfect slug on a thin page does not repair the page.
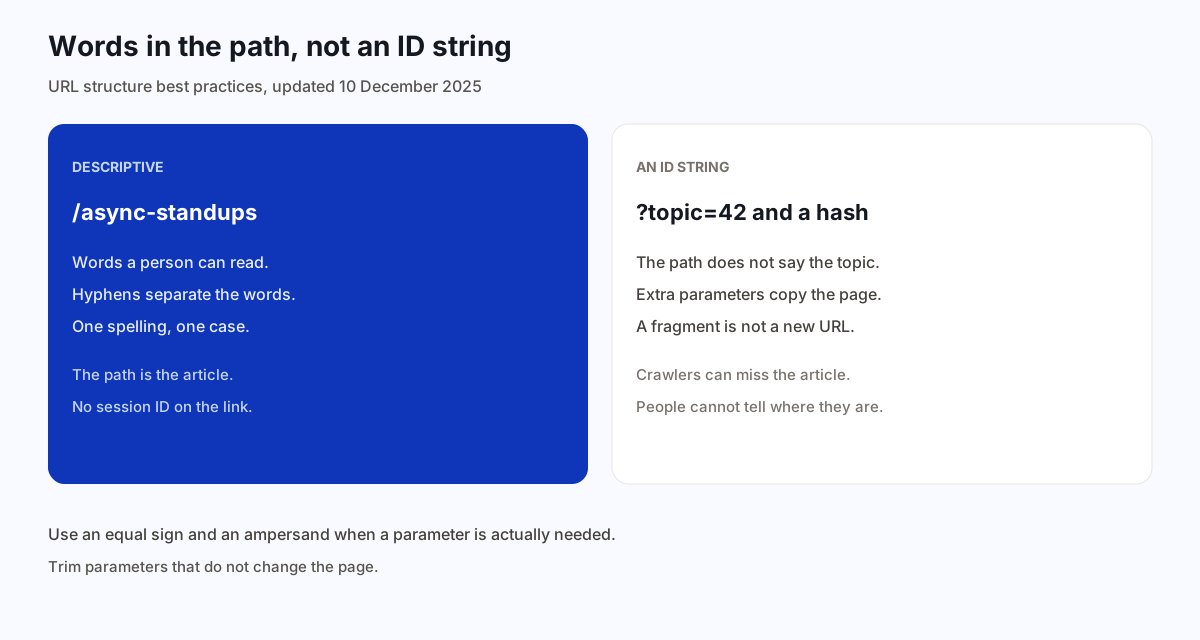
There is no character budget in that documentation. Advice that says a URL must be under a specific count is adding a rule Google’s page does not contain. Very long URLs are a problem when the length is parameters, IDs, and repeated folders, not when a clear compound word needs a hyphen. Shorten by removing what does not change the content. Do not shorten by gluing the words into /asyncstandups so the string looks smaller. People stop being able to see the two ideas.
Folder depth is the same kind of invented rule. Google asks for a structure a human can follow. A guide at /guides/meetings/async-standups can be a sensible tree. A guide at /async-standups can be a sensible tree. Neither depth is a ranking lever this page documents. Pick the tree you will still understand in a year, and link to the article with that path. Do not add empty folders to “build silos,” and do not flatten a real section into the root because someone said the third slash is costly.
| Address | What it does |
|---|---|
/async-standups |
One article. Words. Hyphens. The pattern to keep. |
/async_standups |
Underscores. Google recommends hyphens instead. |
/ASYNC-STANDUPS |
A second URL if you also publish the lowercase path. Pick one case. |
/#/async-standups |
A fragment. Not a separate page Google can reliably crawl. |
?topic=42&area=… |
IDs instead of words. Harder to understand, and easy to multiply. |
Hyphens, language, and case
Separate words with hyphens. Google recommends that over underscores, for a historical reason: underscores are already used in programming to mean “these tokens stay one name,” the way a function might be called format_date. A hyphen reads as a break between concepts. Joining everything, /summerclothing, hides the break. Use hyphens in the path and, when a parameter needs more than one word, hyphens inside that value too. color-profile=dark-grey is their shape. color_profile=dark_grey is the one they mark as not recommended.
Use the audience’s language in the words. If people search in German, the URL can use German words. If they search in Japanese, the URL can use Japanese words. Google’s examples include both. A translated article is not an English slug with a language folder painted on. The words of the path should be words that audience uses. The hreflang guide is how those versions point at each other. The path does not replace the annotation, and the annotation does not choose the words.
Non-ASCII characters in an href should be percent-encoded. Google’s encoding table marks the percent-encoded form as recommended and the raw non-ASCII form in the link as not recommended. Unreserved ASCII can stay as itself. The address bar may still show the decoded words, which is what you want a person to read. Publish one form. If the server answers both the encoded href and a second unencoded URL, you have two addresses. Pick the one you link, and canonicalize or redirect the other. Do not add a third, transliterated slug “for Google” beside the real language. The audience-language section is the instruction. Percent-encoding is how the href is written, not a reason to switch the article to English.
URLs are case sensitive. Google treats /APPLE and /apple as different URLs, each with its own content, because that is what the standard says. If your server folds case and shows the same page for both, convert the text to one case so Google is not left to discover the duplicate on its own. Lowercase is the usual choice because it is easy to type. The requirement is consistency, not a specific case. The other spelling should not remain a second 200. Send it to the spelling you kept.
For a site aimed at more than one country, Google’s URL page suggests a structure that makes the regions easy to tell apart. A country domain such as example.de, or a country folder on a generic domain such as example.com/de/, are the two patterns it marks as recommended. That is the shape of the URL. It is not hreflang, and it is not a claim that a folder ranks in that country by itself. Use the structure, then annotate the versions. A blog in one language does not need a country folder to look international.
Parameters, without a copy of every page
Use as few parameters as you can. The ones to trim are the ones that do not change the content. A campaign code on an article is still that article. A session ID is still that article. A print flag that returns the same sentences is still that article. Each of those is another URL. Google may crawl it. You then need a canonical to point it back, which is extra machinery for a parameter you did not have to put on the link.
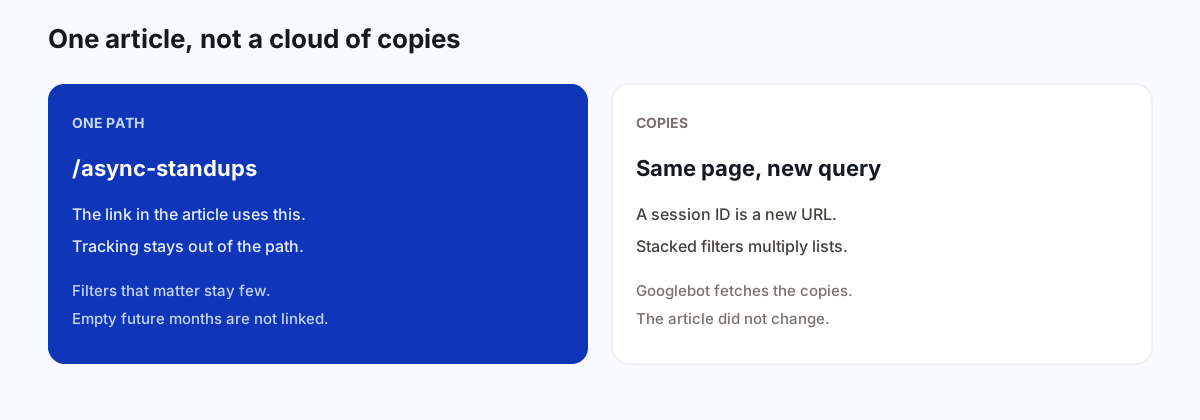
Some parameters are the page. Page 2 of a list is not page 1. ?page=2 is a normal way to say that, and the pagination guide is why each slice keeps its own canonical. A sort that reorders the same slice is usually not a new document. Encoding it as ?topic=standups&sort=newest is the correct syntax if you must have the parameter. Generating every sort, and linking all of them, is how a small blog grows a large URL set. Syntax and necessity are different questions. Get the syntax right, then ask whether the parameter should exist.
Multiple values for one key can sit in one parameter. color=purple,pink is the kind of list Google shows as recommended, next to an equal sign and an ampersand for the other keys. You do not need a private punctuation scheme to mean “and.” If the filter is real, use the common encoding. If the filter is a view nobody asked to find in search, do not give it a URL in your templates.
Fragments are not pages
A fragment does not create a crawlable page. Google’s example of the failure is a hash route such as /#/potatoes. The part after the hash is not sent to the server as a different path. Google generally will not treat it as different content. If JavaScript changes the view, use the History API and a real path. The JavaScript SEO guide is that routing rule in full. This page only needs the URL consequence: /async-standups can be requested, fetched, and indexed. /#/async-standups cannot stand in for it.
In-page links are a different use of the hash. A link to #questions on the same article moves a person to a heading. It does not claim to be another article. Leave those alone. The failure is loading a different document from the fragment, or paginating with #page=2 so the next slice never becomes its own request.
Filters, sessions, calendars, and broken links
Over-complex URLs, especially with many parameters, create large numbers of addresses for identical or similar content. Google’s page says Googlebot may then use more bandwidth than it needs, or Google may be unable to index all of the content. The causes it names are practical.
Additive filters are the first. A directory that lets people combine “beginner,” “remote,” and “under 30 minutes” can generate a URL for every combination. Googlebot does not need every list. It needs a small number of lists from which it can reach each item. A blog index with a few real categories is that small set. A page that emits a URL for every pair of tags is the explosion. Stop emitting the pairs. Do not try to write a unique article for each pair so the URL looks justified.
Irrelevant parameters are the second. Referral codes, sort parameters on a search result, and session IDs each multiply the same page. Google’s recommendation for session IDs is direct: avoid them in URLs and use cookies instead. A cookie can remember the reader without changing the address. A session parameter cannot. If old emails already contain those parameters, the canonical on the parameterized URL should be the clean article, and new links should not add the parameter.
Calendars are the third. A generated calendar can link to every past and future month with no end. Google says that if the calendar is infinite, add nofollow on links to dynamically created future pages. An editorial archive that only links to months you actually published does not need that treatment. A widget that links “next month” forever does. Empty future URLs are not content. They are a crawler trap.
Broken relative links are the fourth. A parent-relative link, the kind that starts with ../, placed on the wrong page, can build paths that were never real. If the server answers those paths with 200 instead of a proper missing-page status, the space can grow without a boundary. Google’s fix is to use root-relative URLs, starting at /, rather than parent-relative ones. /async-standups means the same page from anywhere on the host. ../async-standups means something different on every folder depth. A 200 for a path you did not publish is also a soft 404 problem. The status and the link style both have to be right.
What to block, and what not to block
If Google is already crawling the bad URLs, the URL guide says to consider robots.txt for the problematic ones. The examples are dynamic URLs that only generate search results, infinite spaces such as calendars, and ordering or filtering functions. Faceted navigation is the larger version of the same explosion, because a catalog of filters can become its own URL space. A blog’s version is smaller: do not generate the filter URLs, and do not list them in the sitemap.
robots.txt is the wrong tool for an article you want found. A disallow can leave a URL in results without its content, and it hides any noindex you put on the page. The robots meta guide is that distinction. The crawl budget guide is when a very large site is already at its fetch limit and a disallow is how you stop an infinite pattern. A normal article site is not that case. Blocking /async-standups to “save crawl” does not improve the URL structure. It removes the page.
On a large site, the order of fixes is: stop linking the junk, return a real 404 for paths that are not pages, canonicalize the tracking copies you cannot delete, and only then disallow the patterns you cannot consolidate. Disallowing first, while the template still emits the links, leaves Google with a queue of URLs it is told not to fetch and may still know about. Fix the template. The file is the backstop.
A URL example
Northwind’s standup guide lives at /async-standups. Internal links use that path, root-relative, with hyphens and lowercase. There is no /async_standups, and a request for the uppercase spelling redirects to the lowercase one. The German version, if they publish it, uses German words and a /de/ folder, and hreflang connects the two. The href percent-encodes anything that is not ordinary ASCII. They do not keep an English slug and a German slug both on the English host without a reason.
The old ID URL, /index.php?topic=42, redirects once to /async-standups. It is not canonicalized as a second 200, because the ID address is not a page they want to keep. Newsletter links do not add a session ID. If a campaign parameter arrives from an old send, the article’s canonical is still the clean path. The archive lists months that have posts. It does not link next year’s empty months. Tag combinations are not URLs. The category page is one list, and it links to each guide.
They do not expect the hyphenated slug to raise the guide by itself. They expect a person, and a crawler, to land on one address that matches the H1. When the slug was wrong, they changed it once and redirected. They do not change it again because a newer keyword appeared.
How this shows up when you choose a slug
BloGoose publishes to a path you choose. Choose words a reader would recognize, with hyphens, in one case, without a query string. Leave tracking, drafts, and previews off that path. A preview can be a separate URL that is not the article. The article’s address should still make sense if someone copies it into a message.
After the URL is live and accurate, leave it. A later keyword is not a new path. The content refresh guide is when a slug is actively misleading, and the redirects guide is the one hop that follows. Choosing well the first time is how you avoid that hop. A descriptive URL is a labeling decision. It is not a score, and it is not a substitute for the page.
Questions about URL structure
What is a crawlable URL structure?
A crawlable URL structure follows the URL standard Google supports, uses a real path instead of a fragment to change the page, and encodes parameters with an equal sign and an ampersand. Descriptive words are the recommended form. Long ID strings are not.
Should URLs use hyphens or underscores?
Google recommends hyphens to separate words. It does not recommend underscores, because underscores have long been used in programming to hold a name together, and it does not recommend joining the words with no separator. Hyphens make the concepts easier to see.
Are URLs case sensitive?
Yes. Google treats /Apple and /apple as different URLs. If your server treats those spellings as the same page, pick one case and send the other spelling to it, so Google is not asked to crawl two addresses for one document.
Should you put session IDs in URLs?
No. A session ID creates another URL for the same page. Google recommends cookies for that state. Referral codes and sort parameters that do not change the article have the same problem. Keep the parameters the page actually needs.
Do URL fragments create separate pages?
No. Google generally does not support fragments as a way to change page content. A hash is not a second article. Use a real path, and the History API if the view changes without a full reload.
Should every filtered list be its own URL?
No. Combining filters can create a huge set of near-duplicate lists. Googlebot needs a small number of lists that link to each item, not every combination. Block or stop generating the combinations that are not real pages.
One path, in words, with hyphens. Parameters only when the page actually changes.
Start the 1-day trial