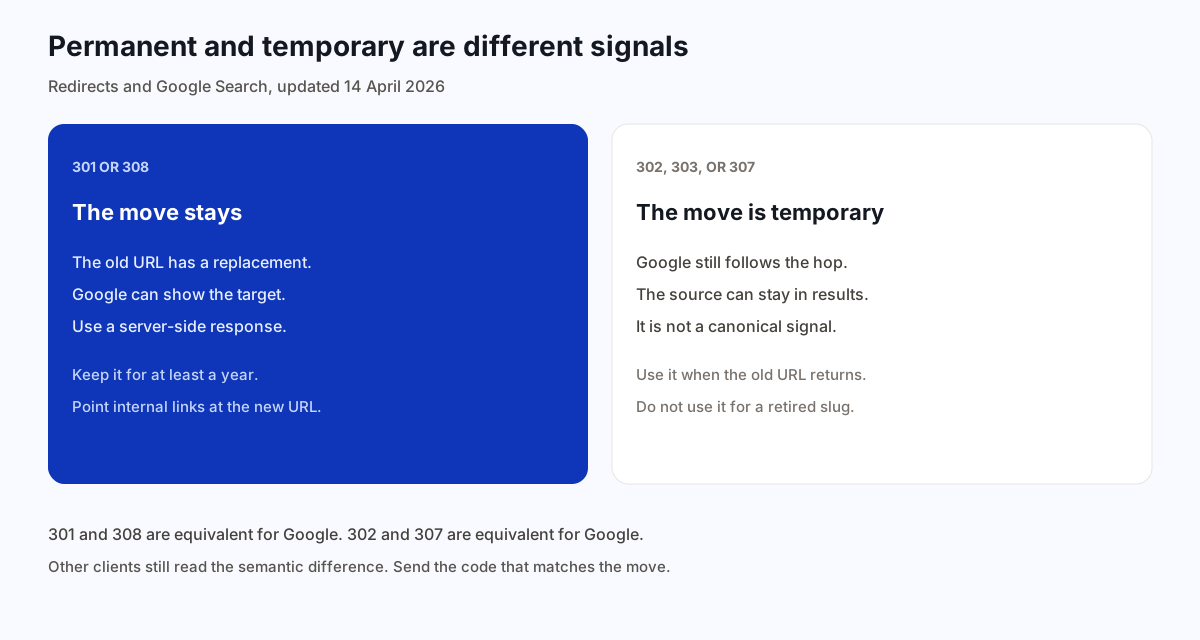
A 301 redirect is a permanent redirect: the server answers an old URL by sending the browser, and Googlebot, to a new one. Google’s redirects documentation, updated 14 April 2026, says a permanent redirect is how you ask Search to show the target. A temporary redirect is followed too, and the source URL can stay the result. The status-code documentation, updated 4 February 2026, adds the crawler view: a 301 is a strong signal to process the target, a 302 is a weak one, 308 is treated like 301, and 307 is treated like 302.
When a URL is retired for good, respond with a server-side 301 or 308 straight to the page that replaced it. Use a 302 only when the old URL will come back. If nothing replaced the page, return 404. Keep a real redirect for at least a year, and point your own links at the new URL so people are not sent through the hop.
What a 301 redirect is
A redirect resolves one URL to another. Visitors and Google Search are told the page has a new location. Google names the situations: you moved the site to a new domain, several URLs reach the same page and you have picked one, you merged two sites, or you removed a page and there is a new page to send people to. A blog hits the last two more often than a domain change. An old slug that no longer describes the article, or a second post you folded into the one you kept, is a redirect. A typo URL with no successor is not.
People usually cannot tell a 301 from a 302. The address bar ends on the new page either way. Google Search uses the type as a signal about which URL should be canonical, meaning which URL it may show. Permanent redirects say: show the target. Temporary redirects say: show the source. That is the decision. The canonical tag is the hint you put on a URL that still returns 200. A redirect is what you use when the old address should stop being a page.
Google’s site-move documentation says not to worry about link credit: 301 and other permanent redirects do not cause a loss in PageRank. Checklists that subtract a percentage on every hop are adding a number that page does not contain. A redirect also does not raise rankings. It tells Google which URL is the one you kept. Expect temporary fluctuation while the new URL is recrawled. The site-move page says a medium site can take a few weeks for most URLs, and a larger site longer. That is a processing window, not a penalty you reverse by switching the code.
Permanent or temporary
Choose the code from how long the move lasts and which URL you want in results. Use a permanent redirect when you are sure you will not revert it. Use a temporary redirect when the old URL should remain the result, for example a service page that is briefly offline and should return.
| Response | How long | What Google Search does |
|---|---|---|
| 301 or 308, server-side | Permanent | Follows the hop. The target can be the canonical URL in results. Strongest method. |
| 302, 303, or 307, server-side | Temporary | Follows the hop. The indexing pipeline does not treat the target as the canonical. The source can stay in results. |
| Meta refresh, delay of 0 | Treated as permanent | Fallback when the server cannot send a 301. Weaker than a server redirect. |
| Meta refresh, delay greater than 0 | Treated as temporary | Fallback. A five-second pause is not a stronger 301. |
| JavaScript location change | Only if nothing else works | Seen only if rendering succeeds. It can be missed. |
| A sentence and a link | Last resort for people | Google may read it as a crypto redirect. Do not rely on it. |
The status-code page says Google treats 308 like 301 and 307 like 302, and that the codes are still semantically different. Other clients, including other search engines and some readers, can use that difference. Send 301 when the move is permanent and 308 only if your stack already speaks 308 for that meaning. Do not pick 302 because a plugin defaulted to it on a slug you will never restore. A year later the old URL can still be the one in results, because you told Google the move was temporary.
There is a wording difference worth keeping. The crawler status-code page calls a 302 a weak signal that the target should be processed. The Search redirects page says a temporary redirect is not a signal that the target should be canonical. Both can be true. Googlebot follows the hop either way. “Process the target” is not the same sentence as “replace the source in results.” For a retired article, you want the second sentence, which is the permanent code.
Server-side first
Google orders the methods by how likely they are to be interpreted correctly. A server-side redirect is first. It is an HTTP status and a Location header, sent before any HTML. The body of the old URL is ignored. The final target is what gets processed. For Google Search, a 2xx response is what can be considered for indexing, and a 2xx does not guarantee indexing. The redirecting URL’s content does not get that chance.
How you configure it depends on the host. PHP can send the status and the location before any output. Apache can use a permanent redirect rule. Nginx can return 301 from the matching location. The pattern is the same: the old path, the status, the absolute URL of the replacement, and then stop. A redirect that prints a paragraph first, and then tries to set headers, fails because the response has already started. Test with a client that shows the status line. You want 301, then 200 on the target, not 200 on the old URL with a script that hops later.
Google’s URL Inspection tool does not follow redirects, even though Googlebot generally follows up to 10 hops for ordinary web crawling. If you inspect only the old URL inside that tool, you may be looking at the redirect response rather than the article. Request the old URL, read the status and the Location, then open the target and confirm it is the page you meant. A redirect to a URL that 404s is a common site-move bug. The mapping has to name a page that exists.
Meta refresh, JavaScript, and a plain link
If the platform cannot send a server redirect, an instant meta refresh is the next option. Google treats a delay of 0 as permanent and a delay above 0 as temporary. Put it in the head, or send the equivalent Refresh HTTP header. A refresh that waits five seconds so a person can read “you are being moved” is the temporary kind. It is a poor way to retire a slug. It also keeps the person on a page you meant to leave.
A JavaScript redirect, setting the location in the head, is only for when server-side and meta refresh are impossible. Google renders with the Web Rendering Service after the crawl, and rendering can fail. If it fails, the redirect is never seen. The JavaScript SEO guide is the rest of that limit: do not make the hop depend on a script when the server can answer. A single-page app that paints the new article on the old URL, without a status code, has not redirected. It has served a 200.
If none of those are possible, tell the person. A short note and a normal link to the new page is what Google calls a crypto redirect. The redirects page compares it to something whose existence can be disputed: not every search engine treats that link as an official redirect. Use it so a human is not stranded. Do not use it as the plan for a URL you want moved in Search. An ordinary link is still a link. It is not a 301.
One hop, kept for a year
Googlebot can follow a chain of up to 10 hops for ordinary crawling. The site-move guide still says to redirect to the final URL directly. If a chain cannot be avoided, keep it low, ideally no more than 3 and fewer than 5. Chains add latency for people, and not every client will follow a long one. Each extra slug you leave in the middle is a chance for a loop, a 404 in the middle, or a hop that points at yet another old path.
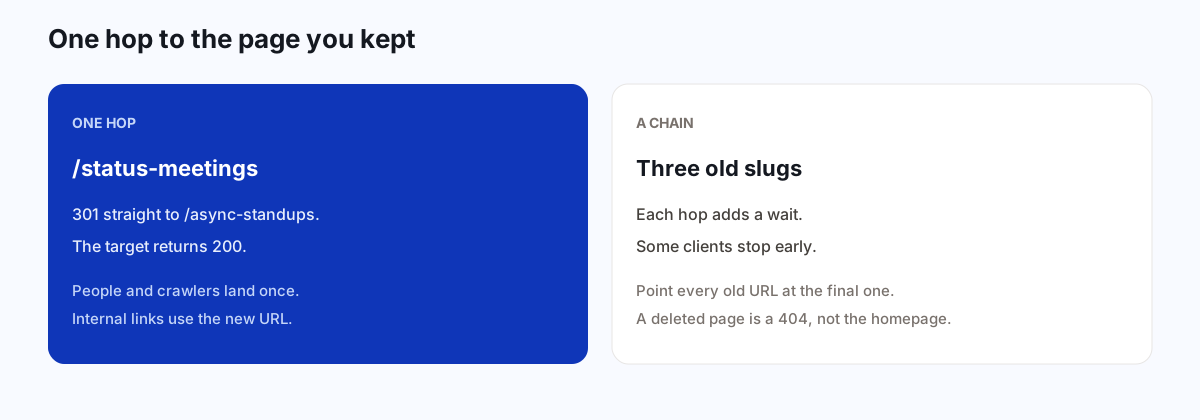
On a large site, long chains also waste crawling, which is the crawl budget note. On a blog, the reason is simpler. A reader who bookmarked last year’s slug should land on the article in one step. Three redirects feel broken even when they eventually work. When you change a slug again, point the original URL at the newest URL, and point the middle URL at the newest URL too. Do not leave original to middle to newest.
Keep the redirects for as long as possible, generally at least one year. That is the site-move timeframe for Google to transfer signals, including recrawling links on other sites that still point at the old URL. From a person’s side, the same page says you may want them indefinitely, because someone will use an old bookmark. Redirects are slower than a direct link, so update your own links, and ask high-traffic sites to update theirs when a domain actually changed. A year is the floor for a real move, not a date after which you delete the rule and hope.
Change of Address in Search Console is only for a move from one domain or subdomain to another. You do not need it for HTTP to HTTPS, for www versus the bare host, or for a path change on the same domain. A slug edit on one article is a path change. The 301 is the tool. The Change of Address tool is not.
What not to redirect
Redirect when there is a replacement. If you removed the page and nothing on the site answers that request, return 404 or 410. Google’s site-move page says the same for content you are not bringing across. A 301 from every deleted post to the homepage makes the report look quieter and lands people on a page that is not the one they asked for. That pattern can itself be treated as a soft 404. The homepage is not a substitute for a missing article.
Do not redirect a URL to a near miss because the titles share a word. “Why status meetings run long” is not the replacement for “how to run an async standup” unless you actually merged those documents. The content refresh guide is when the slug should change: only if the old slug lies about the page you kept. A refresh that keeps the job of the page usually keeps the URL. A redirect is for the address you abandoned, not for every edit.
A 304 is not a move. It means the content is unchanged since the last crawl. The indexing pipeline may recalculate signals, and otherwise the status has no indexing effect. Use it so a crawler can reuse a cached copy. Do not use it, or a 302, when the URL itself has changed. A 5xx is a server failure, not a redirect strategy. Persistent 5xx responses can slow crawling and, for Google Search, can eventually drop URLs that keep failing. Fix the error. Do not paper over it with a hop to the homepage.
Redirect loops are two or more URLs that send the client back to a URL already in the chain. The browser stops. Google stops. A rule that sends /async-standups to /status-meetings while the old rule still sends /status-meetings to /async-standups is a loop you can see by requesting each URL once. One direction. The surviving URL returns 200.
After the hop
Google tracks both the source and the target. One of them becomes the canonical, based on signals such as whether the redirect was permanent or temporary. The other can remain an alternate name. Alternate names are versions of the canonical URL that a person might still trust. They can appear in results when a query suggests the old URL is the one the person knows. After a domain change, Google may still show the old URL sometimes, even though the new URLs are indexed. The redirects page says that is normal, and that the old names fade as people get used to the new domain. You do not fix that fade by deleting the redirect.
On the target, use a self-referencing canonical to the new URL. If you had put noindex on the new URL while it was in preparation, remove it when the redirect goes live. Leaving noindex on the page you want found hides the replacement. Update internal links so navigation, related articles, and the body do not keep sending people through the old slug. A sitemap should list the new URL, not the one that redirects. The XML sitemap guide is that list. Hreflang annotations, if you have them, have to use the new URLs too.
HTTP to HTTPS, and the host you chose versus www, are one-time server rules, not a project inside every article. Pick the preferred origin once. Every other form redirects there in one hop. If the home page redirects, the site name reflects the target Googlebot can fetch. Article canonicals then use that origin. Doing the host redirect inside a plugin on each post is how the rules drift and chains appear.
A redirect example
Northwind retired /status-meetings. The article that replaced it is /async-standups. The server returns 301 with a Location of the standup URL. The standup URL returns 200, canonicalizes to itself, and is the URL in the sitemap. Internal links already say “async standups.” The old URL is not in the sitemap. There is no second hop through /meetings, and there is no 302 left over from a plugin that treated every slug edit as temporary.
They will leave the 301 in place past a year, because old newsletters still use the first slug. They do not expect the redirect to raise the standup guide. They do not point a deleted retro URL at the homepage. That URL returns 404. A temporary outage of the whole site, if it happened, would be a 503 or a maintained page, not a 301 of every article to a holding URL they would then have to undo.
When they tested, they requested /status-meetings and read 301, then requested the target and read 200. They did not stop at the inspection tool, because that tool does not follow the hop. The article people land on is the one that explains the procedure.
How this shows up when a slug changes
BloGoose publishes to a URL you choose. If you later change that slug because the old one is wrong, the old URL needs one permanent server redirect to the new URL, and the new URL needs to be the one in your links and your sitemap. The draft cannot invent that hop inside the HTML of the new article. The hop is a server rule on the old path. If you are only updating the article, keep the URL. A redirect is for an address you are leaving, not for a date change.
Do not add a sitewide rule that sends unknown paths to the homepage. Unknown paths are 404s. Known retired paths, with a real successor, are 301s. Those are different lists. Mixing them is how a missing post and a merged post get the same wrong destination.
Questions about 301 redirects
What is a 301 redirect?
A 301 redirect is a permanent server response that sends a request from an old URL to a new one. Google follows it and can use it as a signal that the target should be the canonical URL shown in search results. Use it when the move will not be reverted.
What is the difference between a 301 and a 302?
A 301 or 308 is permanent: Google Search can show the target. A 302, 303, or 307 is temporary: Google follows it, but the indexing pipeline does not treat the target as the canonical, and the source URL can stay in results. Use the code that matches how long the move will last.
Do 301 redirects lose PageRank?
Google site-move documentation says 301 and other permanent redirects do not cause a loss in PageRank. Keep the redirect in place, generally at least a year, and update your own links to the new URL. A redirect is not a reason to expect a ranking increase.
Should you redirect a deleted page to the homepage?
No. Redirect when a real page replaced the old one. If nothing replaced it, return 404 or 410. A redirect to an unrelated page, including the homepage, can be treated as a soft 404.
How many redirects can you chain?
Googlebot can follow up to 10 hops for ordinary web crawling, and the site-move guide says to send people straight to the final URL. If a chain is unavoidable, keep it low, ideally no more than 3 and fewer than 5. One hop is the pattern for a retired blog URL.
Is a JavaScript redirect as strong as a 301?
No. Use a server-side 301 or 308 when you can. Meta refresh is a fallback: instant is treated as permanent, and a delay is treated as temporary. A JavaScript location change is only for when those are impossible, because rendering can fail and Google may never see it.
One permanent hop, to the page you kept. Leave the old URL in place long enough to be followed.
Start the 1-day trial