Google Discover is a part of Google Search that shows people content related to their interests, based on their Web and App Activity. Discover traffic is the visits that arrive from that feed. Google’s Discover documentation, updated 9 March 2026, says a page is automatically eligible when it is indexed and meets Discover content policies. No special tag is required. The same page says eligibility is not a guarantee of appearing.
Get the page indexed, write it for a person, and give it a large relevant image. Skip clickbait titles and the site logo as the thumbnail. Then treat any Discover visits as extra. You cannot book a keyword position in the feed, and a quiet week is not a defect you fix by changing the date.
What Google Discover is
Search and Discover share a company and a lot of systems. They do not share a job. Search answers a query someone typed. Discover assembles a feed from interests, which can come from search activity and from other Web and App Activity. A person does not have to search “async standup” today for a standup guide to be a candidate. They also do not see a ranked list of ten blue links with that query sitting above them.
That difference is why a Discover checklist copied from a ranking checklist goes wrong. There is no position three to climb. There is no title-tag length that unlocks the card. Guides that sell “Discover keywords” are describing Search and putting the Discover name on it. The feed is interest-based. The page still has to be about something a person would want when that interest is active.
| Question | Google Search | Google Discover |
|---|---|---|
| How someone arrives | They ask a query | The feed follows interests, including Web and App Activity |
| What you can aim at | A page that answers that query | No keyword slot inside the feed |
| What Google requires first | A page it can crawl and choose to index | The page is already indexed, and it meets Discover content policies |
| Special markup | Article schema is optional and must match the page | No special tags or structured data are required |
| What the visits feel like | Tied to queries you can read in Search Console | Supplemental, and less predictable than search |
Content that may appear covers a wide range of topics, as long as it lines up with someone’s interests. Google names articles and videos as the kind of material the feed is built to show. A company blog post can qualify. A form, a petition, or a job application is a poor fit, which is covered below. The page you publish for search is usually the same URL. You do not maintain a second “Discover version” with a louder headline.
Eligibility is not a visit
The sentence worth keeping is short. If the page is indexed and meets the content policies, it is eligible. Being eligible does not mean it will show. Google states that directly. A plugin that scores a draft “Discover ready” because the image is wide has checked one recommendation. It has not reserved a card.
Competitor pages often collapse those two states. They list “how to rank in Discover” and then prescribe a posting frequency, a curiosity gap in the title, and a schema type that does not exist for this feature. The official page has no Discover schema requirement. It has no quota of posts per week. It has a list of practices that raise the chance of appearing, and an explicit note that chance is not a promise.
Older content may appear if it is helpful and relevant to a person based on their interests. A guide from last year is not disqualified because the copyright line says last year. Freshness is one way a page can match a current interest. It is not a rule that every card must be from this week. Changing the visible date to look new, without changing the article, is the habit the content refresh page already warns against. Discover does not create an exception.
The same helpful-content systems
Discover uses many of the same signals and systems Search uses to decide what is helpful, people-first content. Google points publishers at that advice. A page written to manipulate rankings does not become acceptable because the hoped-for click comes from a feed instead of a query. The scaled content abuse guide is the policy line for many pages made mainly to rank. The same line matters here: the test is whether the page helps someone.
People-first, on a single article, is concrete. The opening answers the question the title names. The byline is a real person or the real organization, which is the author page choice. Claims that need a source name the document. A reader who has the interest can finish the page without searching again for the thing the card promised. If the card says the page explains a standup and the page is a list of tool logos, the card was the product and the article was the bait.
Google also asks for an overall good page experience and links its page-experience documentation. That is about whether the page can be read: a stable layout, text that is text, and a page that is not blocked by interstitials. It is not a separate Discover score you paste into the head. Width and height on images, so the article does not jump, already live on the image SEO page. Do not turn Discover into a Core Web Vitals project with a different name.
Answer engines that quote “how to get on Discover” often repeat the schema myth or a made-up click-through threshold. The quotable correction is the official one: indexed, within policy, no special markup required, appearance not guaranteed. Put that in the first screen, in sentences that stand alone, which is what this opening does.
Titles that state the page
Google’s recommendations for the feed start with the preview, because the preview is what a person sees before the click. Use page titles and headlines that capture the essence of the content. Avoid clickbait and similar tactics that inflate engagement with misleading or exaggerated details in the title, the snippet, or the image, or that withhold something the person needs in order to know what the page is about. Avoid sensationalism that plays on morbid curiosity, titillation, or outrage.
Those are content-policy lines, not style tips. “You will not believe this standup trick” withholds the topic and exaggerates the payoff. “How a six-person team runs an async standup” states the page. The title tag guide is how that sentence should sit in the title element and the H1. Discover reads the same words as preview content. A title written only to win a curiosity click fails the Discover recommendation and the title-link recommendation at once.
Timely content, a story told well, or a unique insight are the positive versions Google names. A procedure your team actually uses is an insight a generic roundup does not have. You do not need a news hook. You need the page to be specifically about the thing the headline says, with something on it that a copied outline would miss. Inventing a statistic to sound timely is the opposite. Answer engines will quote the number, and you will not have a source.
The image Discover can use
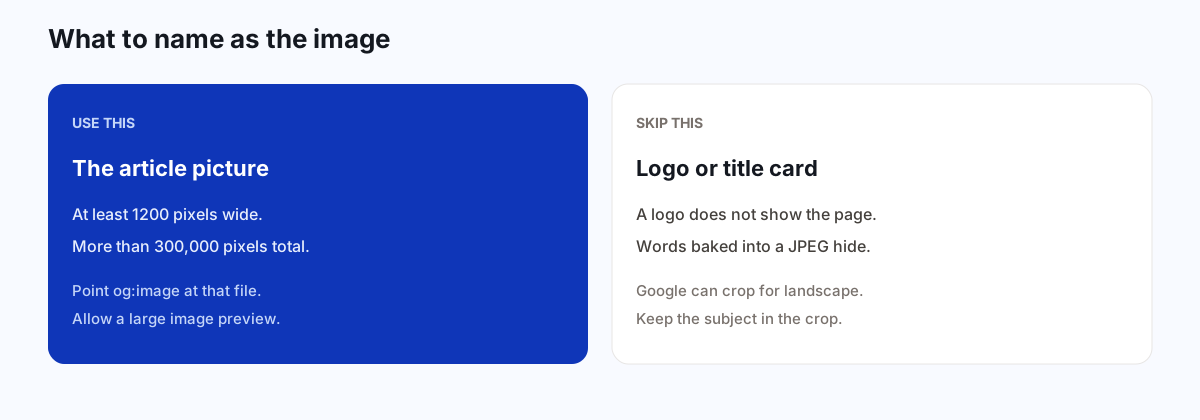
Large, relevant, high-quality images are more likely to generate visits from Discover. Google recommends images that are at least 1200 pixels wide and more than 300,000 pixels in total. The example on the page is a 16:9 image at 1280 by 720, which has 921,600 pixels and meets that bar. Google tries to crop the image for the feed. If you crop it yourself, keep the important part inside the landscape frame, and put that file in the image you specify. Cutting a vertical photo down to a wide strip and losing the subject is the failure mode they describe.
Specify the image with schema.org markup or an og:image meta tag. Either can influence which file becomes the thumbnail. The article image property, when it matches the picture on the page, is the schema path. The article schema guide is how that property should repeat a real image, not a logo. Avoid a generic image such as the site logo in that markup or in og:image. For best results, also avoid a text-heavy image. A title card that repeats the H1 in pixels gives Discover words it cannot read as a picture of the subject, and it gives a reader nothing the headline did not already say.
Large previews are enabled by max-image-preview:large, or by using AMP. AMP is an alternative Google still names. It is not a requirement for a normal article. The robots meta documentation says that if you do not set max-image-preview, Google may show a default-size preview, and that large allows a preview up to the viewport width, including in Discover. The robots meta page is the rest of that family: nosnippet also applies to Discover, and it is the wrong switch on an article you hope will be shown. Set the large-preview value if you want the large thumbnail. Do not add nosnippet on the same page and then wonder why the card has nothing to say.
The image file has to be crawlable. A picture blocked in robots.txt, or hosted where Google cannot fetch it, cannot be the thumbnail. Alt text still describes the image for the article, which is image SEO, not a Discover keyword. The answer the page teaches stays in HTML. A JPEG is an illustration. It is not the only copy of the steps.
What the feed tends to skip
Discover tries to show material that fits an interest-based feed and to filter material that is unwanted or confusing. Google’s examples are job applications, petitions, forms, code repositories, and satirical content without context. A blog post that is actually a lead form with three sentences above the fields is close to that list. A real article that links to a form at the end is not the same thing. The page has to be the article.
Discover uses SafeSearch and also filters content that might be seen as shocking or unexpected. That is a product decision about the feed, not a request to make every topic bland. It is a reason to avoid a preview that shocks and a page that does not match the preview. If the subject is sensitive, the title should still say what the page is, in ordinary language, so the card is not a surprise.
Sports, health, entertainment, and lifestyle are examples Google gives of topics the feed regularly shows. They are examples, not an allowlist. A product-team guide is not blocked because it is none of those four. It appears, if it appears, because it matches an interest and clears the policies. Do not retitle a standup procedure as a health story to chase a category name.
Why Discover traffic moves
Google says Discover traffic is less predictable than keyword-driven search and should be treated as supplemental. The documented reasons it fluctuates are specific.
- Changing interests. The feed is built to follow what a person is interested in, partly from search activity. If they search for a topic less, the feed can show other interests. Publisher traffic can move because of that, without a change to the article.
- Content types. Discover adjusts the kinds of content that appear, to match what people are looking for. A topic that was common in the feed can be less common later.
- Updates to Search. Because Discover is part of Search, a Search update can change Discover traffic. Google points publishers at its core-update documentation when performance changes after an update.
The follow-up sentence matters as much as the list. Google says there may be nothing you need to do after an update. Work on the Discover experience means sites can see traffic changes that are unrelated to the quality of the content or to how often they publish. A drop is not an order to publish twice as often. A spike is not proof that the clickbait title was the cause, and it is not a quota you must hit again next week.
The wrong response is a date change on every quiet URL, or a batch of near-copies aimed at the interest you think the feed wants. The first fails the helpful-content question about fake freshness. The second is the scaled-content problem. If a page is outdated, refresh the passage. If it is fine, leave it. Search traffic is still the channel you can tie to a query.
The Discover performance report
When a site has content on Discover, Search Console has a Performance report for Discover. It shows impressions, clicks, and click-through rate for content that appeared in the last 16 months, once the data reaches a minimum threshold of impressions. Google says the report includes traffic from Chrome and fully tracks Discover traffic across the surfaces where people use Discover.
Read it as a record, not as a score you optimize in isolation. A high click-through rate on a misleading title is the pattern the content policies tell you to avoid. A week with no rows can mean the page was not shown, or that impressions stayed under the threshold. It does not mean the article should be noindexed, rewritten into a teaser, or given a new URL. Compare it with the search performance of the same URL before you decide the page failed. Many useful articles never appear in the feed and still earn their search visits.
Do not invent a target click-through rate. Google does not publish one on the Discover page. Third-party posts that name a percentage you must beat are adding a number the documentation does not contain. Report what you measured on your own property. Leave everyone else’s percentage out of the article.
A Discover example
Northwind’s standup guide is one URL, indexed, with a title and an H1 that both say how a six-person team runs an async standup. The opening paragraph states the method. Priya Shah’s byline matches the author page, or the organization is the author if the company signs it. The figure is the board, exported wider than 1200 pixels, with the subject still visible if the image is cropped landscape. og:image and the article schema image point at that file, not at the Northwind logo. The robots meta value allows a large image preview. The page does not use nosnippet.
They do not publish a second headline for the feed. They do not add a “Discover” schema block. They do not change the updated date on a quiet Tuesday. If the procedure itself changes, they edit the steps and then move the date, which is a content refresh. If Search Console later shows Discover impressions, they read them as supplemental. If it never does, the guide still has a job in ordinary search.
A bad version of the same URL would use the logo as og:image, title the page “This meeting trick is unbelievable,” and hide the steps inside a text image. That version fails the image recommendation, the clickbait line, and the rule that the article’s answer has to be in HTML. It can still be indexed. Eligibility would be the wrong word for it.
How this shows up on a published post
When BloGoose publishes to your site, the post should be normal HTML: a title that matches the H1, a representative image with width and height, and a canonical URL that is the one you want indexed. Discover eligibility follows indexing. It does not follow a separate export. If the destination theme replaces the image with the site logo in og:image, fix the theme. The draft cannot override a template that throws the picture away.
Review the title the way you review any title. It should capture the page, which is the title-tag standard and the Discover standard together. Leave nosnippet off. Allow a large image preview if you want the large thumbnail. Then publish for the query the article answers. Check Discover in Search Console when there is something to check. Do not hold the article until a feed appearance shows up. Google has already said that appearance is not guaranteed.
Questions about Google Discover
What is Google Discover?
Google Discover is a part of Google Search that shows people content related to their interests, based on their Web and App Activity. A page is eligible when it is indexed and meets Discover content policies. Eligibility does not guarantee that the page will appear.
Does Discover require special schema?
No. Google says no special tags or structured data are required. You can point at a large image with schema.org markup or an og:image meta tag, and that can influence the thumbnail. The markup does not put the page in the feed.
Why does Discover traffic fluctuate?
Discover traffic is less predictable than visits from keyword search. Interests change, the mix of content in the feed changes, and updates to Search can change Discover because Discover is part of Search. A drop does not, by itself, mean the article got worse or that you should publish more often.
What size image does Discover recommend?
Google recommends a relevant image at least 1200 pixels wide, with more than 300,000 pixels in total. A 1280 by 720 image is the example on the page, because it has 921,600 pixels. Do not use the site logo or a text-heavy card. Large previews also need max-image-preview set to large, which the robots meta guide covers.
Can an older article appear in Discover?
Yes. Google says older content may appear if it is helpful and relevant to individual interests. Changing the date without changing the article is not what that sentence asks for. Update the passage first. The content refresh guide is that edit.
Should you optimize a page for Discover traffic?
Treat Discover traffic as supplemental. Google says it is less predictable than keyword-driven search, and being eligible is not a guarantee of appearing. Write the page for a person, keep it indexed, and supply a representative image. There is no keyword position to win inside the feed.
Write the page for a person. Let Discover be extra, if it happens.
Start the 1-day trial