A crawl budget is the set of URLs Google can and wants to crawl. Crawl demand is the “wants” half: how much Googlebot, or another Google crawler, wants from that host. Google’s crawl-budget guide, updated 22 July 2026, is written for very large and frequently updated sites. The opening tells everyone else to stop reading it. If your pages are crawled the same day they are published, keep your sitemap current, check the Page Indexing report, and spend your time on the article.
Most blogs do not have a crawl-budget project. The work starts when the site is huge, changes very fast, or has a large share of URLs stuck in “Discovered - currently not indexed.” Even then, crawling is not a ranking signal. Cutting duplicate URLs and server errors helps Google fetch the pages that matter. It does not buy a higher position.
What a crawl budget is
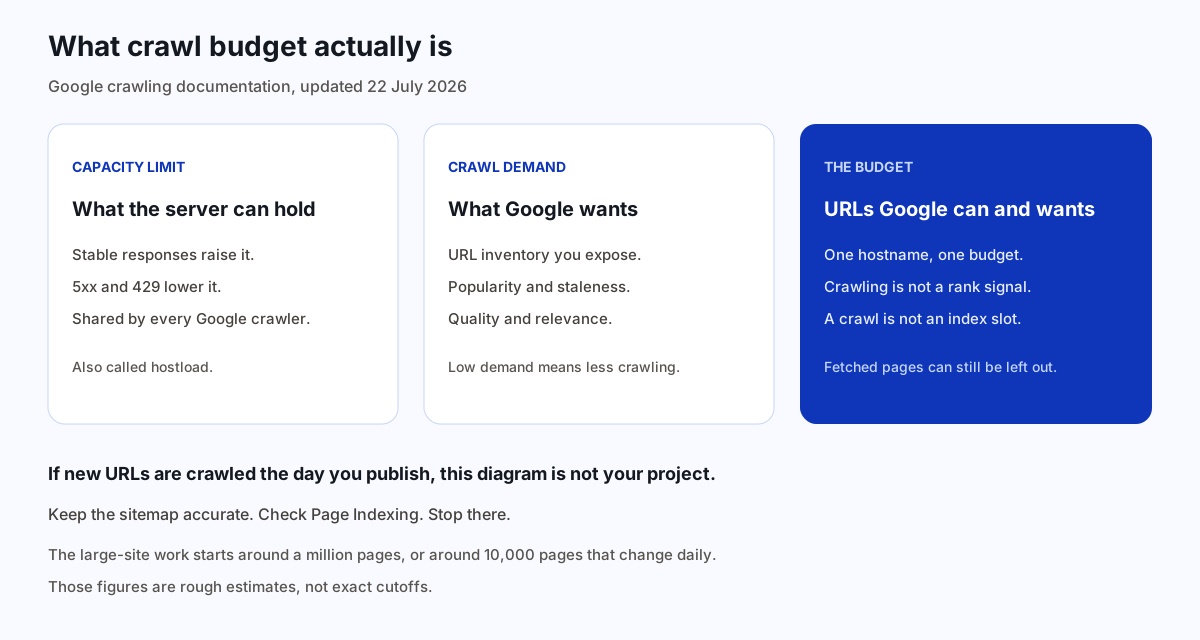
The web is larger than Google can fetch in full. The time and resources it will spend on one site are limited. Google calls that allocation the crawl budget, and it defines a site as one hostname. https://www.example.com/ and https://code.example.com/ are separate sites with separate budgets. A blog on the main host does not share a single pool with a docs subdomain, and fixing one does not automatically fix the other.
Two parts set the budget. The crawl capacity limit, also called hostload, is how much crawling the server can take without being overwhelmed. Crawl demand is how much a given crawler wants. Google’s summary is the set of URLs it can and wants to crawl. If demand is low, Google crawls less even when the capacity limit has not been reached. A fast server does not force more crawling of a site Google has little reason to revisit.
Competitor guides often replace that definition with a formula and a page-count table, then tell every site to “optimize crawl budget” so rankings improve. Google’s crawling myths page says the opposite about rankings: improving crawl rate will not necessarily lead to better positions. Crawling is necessary for a page to be in results. It is not a ranking signal. Search Engine Land’s crawl-budget guide describes the two parts accurately and then ties the budget to how well a page can show up. That last step is the part Google does not make. Fetching is the entrance. Ranking is a different set of systems.
Who the large-site guide is for
Google says the recommendations are generally good practice, and that the guide is still an advanced document aimed at three groups:
- Large sites, on the order of 1 million unique pages, with content that changes moderately often, about once a week.
- Medium or larger sites, on the order of 10,000 unique pages, with content that changes very quickly, about daily.
- Sites with a large portion of their URLs in Search Console as Discovered - currently not indexed.
The numbers are a rough estimate for classifying a site. Google says they are not exact thresholds. A company blog with a few hundred posts is not in the first group because a tool rounded it up. A news site that publishes all day on tens of thousands of URLs can be in the second group without hitting a million. Read the shape of the site, not a leaderboard.

For Google Search on a site outside those groups, Google’s own substitute is an up-to-date XML sitemap and a regular look at Page Indexing. That is the whole assignment. Log-file platforms, crawl-budget scores, and a quarterly “indexation sprint” are optional products. They are not the next step after you publish a post.
Crawl capacity limit
Google wants to crawl without taking the site down for everyone else. The capacity limit is the time your server spends holding connections open for Google, counting both how many connections run at once and how long they last. Every site starts from the same conservative default. If there is demand to crawl more and the site stays healthy, the limit can rise on its own.
Health, in this document, is concrete. If responses stay consistent and response times, including latency and time to first byte, stay stable or improve, the limit can go up. If the site slows, or it answers with server errors (5xx) or rate-limit signals such as HTTP 429, the limit goes down and Google crawls less. Google’s own crawling resources are also finite, so a healthy site is still one site among many.
The capacity limit is shared by all Google crawlers on that hostname. AdsBot can want more when a site runs dynamic ad targets. Google Shopping can want more for products in a merchant feed. High demand from one crawler can leave less capacity for the others. A content blog with no ads and no product feed can ignore that split. A large shop cannot assume Googlebot’s share is reserved.
The myths page adds a practical note about speed. Faster pages can mean more URLs fetched in the same time, and time spent rendering counts as much as time spent requesting. An empty app shell spends that render before the article exists, which is the JavaScript SEO problem. Google may still spend longer on a slower site that has more important information. Making the site fast for readers matters more than making it fast in the hope of crawl coverage. A huge hero image is an image-SEO problem for the reader first. It is not a crawl-budget lever on a forty-page blog.
Crawl demand
Each crawler has its own demand. For Googlebot, demand varies with the site’s size, how often it updates, page quality, and relevance, compared with other sites. The factors Google says you can influence are these:
- Perceived inventory. Without guidance, Google tries to crawl all or most of the URLs it knows on the host. Duplicates, removed URLs, and unimportant URLs spend that time. Google calls this the factor you can positively control the most.
- Popularity. URLs that are more popular on the web tend to be crawled more often so they stay fresh in Google’s systems.
- Staleness. Systems try to recrawl documents often enough to pick up changes.
A site move can also raise demand for a while, so the new URLs get reprocessed. That is a reason to keep redirects short and honest during a move, not a reason to shuffle URLs on a calm blog. Long redirect chains have a negative effect on crawling. One permanent redirect from an old slug to the page you kept is the pattern. The redirects guide is the 301 versus a temporary code, and the canonical tag page is the hint you use when both URLs still return 200. A chain of three hops is the pattern to remove if you are actually in the large-site group.
Quality shows up again when Google explains how to get more budget. For Google Search, the resources allocated to a site factor in popularity, overall user value, content uniqueness, and serving capacity. You raise demand by publishing pages people use, not by requesting crawls of the same page under a new parameter. The myths page says a versioned URL can attract a recrawl, and that it wastes crawl resources when the content did not meaningfully change. Change the URL when the page changed. Otherwise leave it.
There is no extra value in trivial edits that make a page look fresh, including a new date on an unchanged article. The myths page states that for crawling. The content refresh page states it for readers. Both say the same thing: update the passage when the passage is wrong. Do not touch the date as a crawl tactic.
A crawl is not an index slot
For Google Search, not every crawled page is indexed. After the fetch, the page is evaluated, consolidated, and assessed. A URL can be fetched and still be left out because it is a duplicate, thin, or a soft error. “Discovered - currently not indexed” on a large share of a huge site is one reason to read the crawl-budget guide. The same report row on a handful of tag archives is not proof that the host is out of budget. It is a reason to look at whether those URLs should exist, which is an SEO content audit question, and whether they are copies of the posts they list.
Asking Google to index one URL does not raise the budget, and it does not override a noindex. The indexing setup is that tool. Use it when the live page is the version you mean. Do not use it as a substitute for cutting a pile of duplicate addresses.
URL inventory
Inventory is the lever Google highlights. Consolidate duplicates so crawling spends time on unique content rather than unique URLs. Tracking parameters, print views, and a second slug for the same article are the canonical-tag problem. Session IDs and filter combinations that do not change the article are the URL structure problem behind that inventory. Sort and filter copies of a blog index are the pagination problem. Each ?order= variant is another URL Google may try to fetch. On a large catalog those combinations explode. The faceted navigation guide is that explosion when the filters change which items appear. On a blog they are still waste, and the fix is the same: do not give the sort its own indexable URL.
Keep the sitemap updated, and include lastmod when you know the page changed. Google reads the sitemap regularly. The file is the list of URLs you want crawled. It does not enlarge the capacity limit, and zipping it does not either. The myths page says a compressed sitemap still has to be fetched, so you do not save meaningful crawl effort that way. An accurate date helps Google notice a real change. A date stamped “today” on every URL teaches the field to be ignored, which the sitemap guide already covers.
Pages that load and render faster can let Google read more from the site, if you are in the group where that matters. Support 304 Not Modified when a page has not changed since the last crawl, so Google can reuse the cached copy and your server skips the full response. That is a hosting behavior, not a meta tag. Fix it when the server is actually straining. Do not block a publishing calendar on it.
noindex still costs a fetch
This is the point most checklists get backwards, because two Google pages answer two different goals.
If the goal is “this URL must not be a search result,” use noindex and leave the URL crawlable. Google has to fetch the page to see the tag. The myths page says to keep using noindex for that purpose and not to worry about crawl budget. Over time, URLs that leave the index can leave the crawler more room for other URLs. The robots meta page is the decision: thank-you screens, previews, and internal search can be noindex. Articles you want found cannot.
If the goal is “stop fetching URLs we do not want crawled at all,” the large-site guide says noindex is the wrong tool, because Google still requests the URL and then drops it, which wastes the request. It names robots.txt for pages such as infinite-scroll duplicates and differently sorted copies of the same page, when you cannot consolidate them. A disallow prevents the crawl and greatly lowers the chance those URLs get processed further. It also says not to use robots.txt as a temporary way to move budget onto other pages. Google will not shift the newly available budget unless the site is already hitting its crawl capacity limit. Blocked URLs stay in the crawl queue much longer than URLs that return 404, and they get crawled again when the block is removed.
Put the two goals side by side before you edit robots.txt. A disallow is not a reliable way to keep a URL out of results: a blocked URL can still be indexed from links elsewhere, without its content. That limit is why the pagination guide prefers noindex for a sort URL on a normal blog, and why it tells you not to disallow ?page=. On a million-URL site that is already at hostload, robots.txt for the sort pattern is the tool the crawl-budget guide names, and you accept the residual indexing risk or you noindex the URLs you can still afford to fetch. Do not disallow the articles. Do not noindex them to “donate” their crawls to the homepage. On a site that is not at the capacity limit, that donation does not happen.
404s, soft 404s, and server errors
A page that is gone should return 404 or 410. Google will not forget a URL it knows, but a 404 is a strong signal not to crawl it again. The myths page says 4xx responses other than 429 do not waste crawl budget: Google tried, received a status, and received no other content. 429 is the exception because it is a rate-limit signal and it pulls the capacity limit down, along with 5xx errors and timeouts.
A soft 404 is the expensive version. The server says 200, the body says the page is missing or empty, and Google keeps crawling it. The crawl-budget guide tells large sites to eliminate those. The status-code fix is the same on a small site, for a different reason: a 200 “not found” page can be treated as a real URL. Fix the code because it is the wrong code. The budget sentence is the extra reason on a host that is already short of fetches.
Watch the Crawl Stats report in Search Console if the host is large enough that errors show up as a pattern. A spike of 500s during a bad deploy is a capacity problem. A single 404 for a deleted draft is not. Add server resources when URL Inspection reports hostload exceeded and the business actually needs more crawling. Buying a bigger server for a blog that is already crawled the same day does not create rankings.
Myths that waste a week
| Claim | What Google’s crawling pages say |
|---|---|
| Crawling more will rank the page higher | Crawl rate is not a ranking signal. Crawling is required for a page to be eligible to appear. |
| Every site must manage crawl budget | If new pages are crawled the day they publish, you do not need the large-site guide. |
| noindex frees the budget immediately | Google must fetch the URL to see noindex. Budget moves to other URLs only when you are already at the capacity limit, and even then robots.txt is the tool for URLs you do not want fetched. |
| 404s waste the budget | 4xx other than 429 do not. Soft 404s, which return 200, do keep getting crawled. |
| A sitemap or a zipped sitemap increases the budget | The sitemap is a list. Compression does not add capacity or demand. |
crawl-delay in robots.txt slows Googlebot |
Google’s crawlers do not process that non-standard rule. |
| nofollow keeps a URL out of the budget | Any other link without nofollow can still get the URL crawled. |
| Pages closer to the homepage rank better because they are crawled more | Links from the homepage can mean more frequent crawling. Google says that does not mean those pages rank higher. |
| Small sites are crawled less because they are small | Important content that changes often is crawled often, regardless of size. |
| Tweaking a page and updating the date earns a recrawl benefit | There is no additional value in trivial changes that make a page look fresh. |
Query parameters are crawlable. Google does not refuse them because they look messy. If the parameter is a duplicate, canonicalize it or stop linking it. If it is a new page, it is part of the inventory. “Clean URLs” are easier for people. They are not a crawl switch.
A crawl budget example
Northwind’s blog has a few dozen guides. A new post is fetched the day it goes live. The sitemap lists the canonical URLs and updates lastmod when an article actually changes. Page Indexing is quiet. This site does not need a crawl-budget audit. A plugin that scores the homepage “low crawl budget” is scoring a label Google reserved for a different size of site.
The one inventory habit worth cleaning up is not a budget emergency. /blog?order=oldest and similar sorts should not be separate indexable URLs. Pagination already covers that: noindex the sort, or do not generate it, and leave ?page=2 crawlable with its own canonical. A deleted retro guide should return 404, not a soft 404, so it is not fetched forever as a successful page. Neither fix is a ranking project. Both are accurate responses.
If Northwind later ran a store with hundreds of thousands of filter URLs, and URL Inspection showed hostload exceeded while new products sat undiscovered, then the large-site list would apply: consolidate duplicates, stop emitting endless sorts, return real 404s, calm the 5xx rate, and only then talk about capacity. The blog guides would still not be noindexed to feed the store. They are a different job, and if they lived on another hostname they would be a different budget entirely.
How this shows up when you publish
BloGoose publishes an article to a site you already run. One new URL, linked from the pages that mention it, listed in the sitemap if you want it crawled, with a canonical tag that matches the link. That is the small-site path, and it is the right path until the destination site matches Google’s large-site description. Publishing more articles does not create a crawl-budget problem by itself. Publishing thousands of near-copies would be a quality problem first, which is scaled content abuse, and an inventory problem only after the URLs exist in those volumes.
If the destination site is already huge and new posts sit for a long time in Discovered - currently not indexed, look at the host, not at the draft. Duplicate parameters, soft 404s, and 5xx responses are the documented wastes. A title tweak will not move hostload. Check Crawl Stats and Page Indexing, fix the URLs that should not be fetched, and keep the article’s own URL easy to reach with a normal link.
Questions about crawl budget
What is a crawl budget?
A crawl budget is the set of URLs Google can and wants to crawl. It has two parts: a crawl capacity limit, so crawling does not overload the server, and crawl demand, which is how much Google wants to crawl. If demand is low, Google crawls less even when the capacity limit has not been reached.
Does every site need crawl budget work?
No. The Google crawl-budget guide, updated 22 July 2026, says that if pages seem to be crawled the same day they are published, you do not need that guide. For Google Search, an up-to-date sitemap and a look at the Page Indexing report are enough on a site like that.
Is crawl rate a ranking factor?
No. The Google page on crawling myths says improving the crawl rate will not necessarily lead to better positions in search results. Crawling is necessary for a page to appear. It is not a ranking signal.
Does noindex save crawl budget?
Google still has to request the URL to see a noindex tag, so that request is not avoided. Use noindex when the URL should not be a search result. The crawl-budget guide says a very large site should not use noindex to shift crawling onto other URLs, because that shift happens only when the site is already at its crawl capacity limit. The robots meta guide is the index decision.
Do 404 errors waste crawl budget?
A normal 404 or 410 does not. The crawling myths page says 4xx status codes other than 429 do not waste crawl budget, because Google received a status and no page body. A soft 404 returns 200, so it keeps being crawled. Return a real 404 for a page that is gone.
Can an XML sitemap increase crawl budget?
No. A sitemap lists the URLs you want crawled. It does not raise the capacity limit or create demand. Compressing the sitemap does not increase the budget either. An accurate lastmod helps Google notice a real change. The XML sitemap guide is that list.
If the new article is crawled the day you publish, the budget is not the bottleneck.
Start the 1-day trial