Faceted navigation lets a visitor change how a list is shown: products, articles, or events, narrowed by properties. A filter URL is the usual way that change is stored, with each property in the query string. Google’s faceted-navigation crawling guide, updated 18 December 2025, says that pattern can generate an infinite URL space. Crawlers treat those addresses as new until they have fetched them, so they fetch a very large number before deciding the URLs are useless. The fetches spent there are fetches not spent on new pages that are useful. The pages also cost the server, because each combination may be rendered.
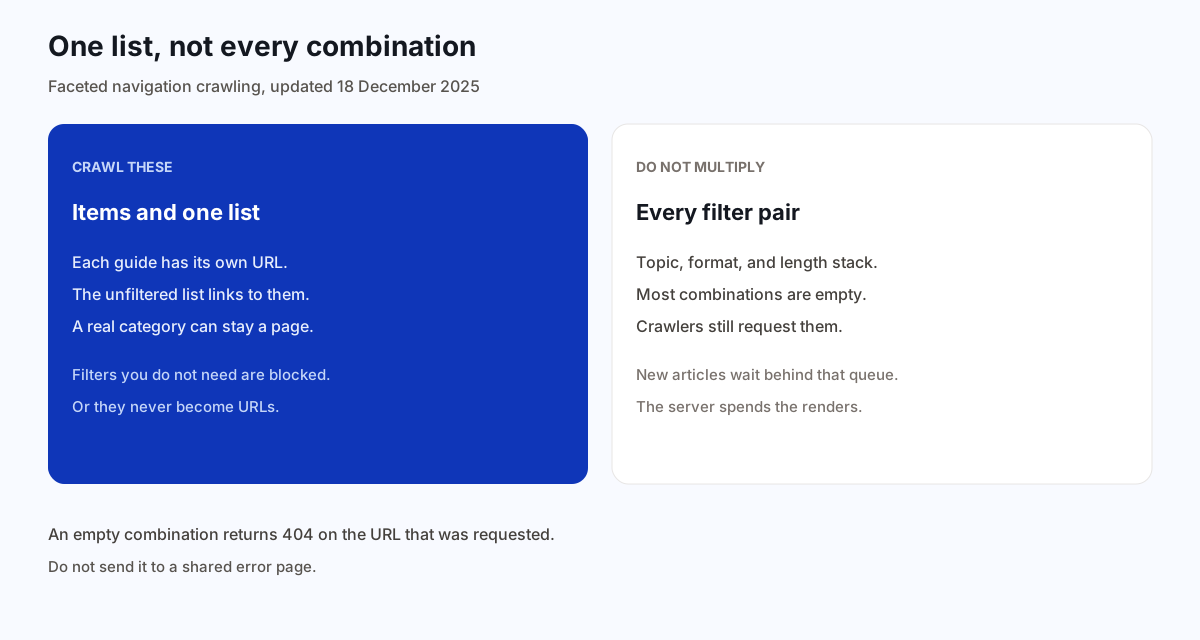
If you do not need the filtered lists in search, do not let them become crawlable URLs. Crawl the items and one unfiltered listing. If a combination has no results, return 404 on that URL. A canonical tag can point duplicates together, and it is a weaker way to shrink the crawl than not creating the URLs.
What faceted navigation does to URLs
A typical filter URL names the properties in the query. Change topic, format, or length and the list changes. Three filters with a handful of values each are already dozens of URLs. Ten filters are a catalog no one will read and a crawler will still try. The harm is not that filters exist for people. The harm is that every combination is an address Googlebot can discover from a link, a sitemap, or another filter link on the page.
Google names two effects. Overcrawling: the URLs look novel, so crawlers access a very large number before their processes decide the URLs are useless. Slower discovery: time spent on those URLs is time not spent on new, useful ones. On a small blog this is waste. On a large catalog it is also a crawl budget problem, because the host only has so much fetching to give. You do not fix it by buying the idea that every long-tail filter is a landing page. Most combinations are the same items, reshuffled, or no items at all.
Two choices, before any tag
Google splits the work in two. If you do not need the faceted URLs potentially indexed, prevent crawling. If you do need them potentially indexed, make the URLs follow the best practices on that page, and accept that crawling them tends to cost a large amount of computing resource because of the number of URLs and the work to render them. There is no third option where every combination is both indexed and free.
| You need the filter in search | What to do |
|---|---|
| No | Do not link a crawlable URL for it. Disallow the parameter pattern, or keep the filter in a fragment so it never becomes a request. |
| Yes, one real category | Give that category one stable URL. Use a normal parameter separator. Return 404 when the combination is empty. |
| Yes, every combination | Google’s page says this costs the server and can slow discovery. Most blogs do not have a reason to choose it. |
Decide per filter, not per site slogan. A category people search for, with its own introduction, can be a page. A control that only re-sorts that category is not a second page. The URL structure guide is why extra parameters that do not change the document should not be minted. This page is what to do when the parameters do change the list, and the lists multiply.
When the filters should not be results
If the goal is to save server resources and you do not need the filtered URLs in Google Search or other Google products, prevent the crawl. Google’s first method is robots.txt: disallow the faceted patterns, and allow the individual item pages plus a dedicated listing that shows the items without those filters. A blog equivalent is: allow /async-standups and /guides, and disallow the query patterns that only mean “and also this format.” Do not disallow /guides itself. Do not disallow the articles. The robots meta guide is the limit on this tool: a disallowed URL can still be indexed from links elsewhere, without its content. So do not link the filter URLs you disallowed, and do not put them in the sitemap. Disallow is for URLs you do not want fetched. It is a poor substitute for noindex on a URL you still want Google to see and then drop.
The second method is a fragment. Google Search generally does not support fragments for crawling and indexing. If the filter lives after a hash, it has no impact on crawling, positive or negative. The list URL stays one URL. People can still toggle a view in the browser. That is the opposite of using a fragment to publish a separate article, which the JavaScript SEO guide says not to do. A hash filter is a way to avoid a second URL. It is not a way to get a filtered list into the index. If you want the filtered list found, give it a real path.
Pick one of those two when the filter is not a page. Do not do both in a contradictory way, such as a crawlable parameter that the template also copies into a hash. One mechanism. The listing remains linked with a normal href.
Canonical and nofollow are weaker
Google also mentions rel="canonical" and rel="nofollow" as ways to signal which faceted URLs to crawl. It says these are generally less effective in the long run than robots.txt or fragments.
A canonical can, over time, decrease the crawl volume of the non-canonical versions. The example shape is a heavily filtered URL whose canonical is a shorter filter, or the unfiltered list, when those URLs are the same list for your purposes. Use that when the filtered address should keep returning 200, because a person or a campaign needs it, and you still want one list in search. The canonical tag guide is that hint. It is not how you delete a combination from the site. If the combination should not exist, do not canonicalize it into a different list and call the problem solved. Crawlers may still request it for a long time.
nofollow on links to filtered results can help, with a strict condition: every anchor that points at that URL must carry nofollow, or the signal does not hold. One template that forgets the attribute, or one external site that links normally, defeats it. That is why Google treats it as the weaker tool. It is also easy to break internal discovery of a list you later decide is real. Do not nofollow the links to the articles. The citing sources guide is nofollow on outbound links you do not vouch for. Here the attribute is about your own filter URLs, and only if every internal link agrees.
When a filtered list should be a page
If you need the faceted URLs crawled and maybe indexed, Google asks you to limit the damage. Use the standard parameter separator, an ampersand, between parameters. Commas, semicolons, and brackets are hard for crawlers to detect as separators, because most of the time they are not separators. A key and a value still use an equal sign. That is the same encoding rule as the URL structure guide. A private punctuation scheme does not make the filters more precise. It makes the URL harder to parse.
If you encode filters in the path, such as /guides/meetings/checklists, keep the logical order stable and do not allow the same filter twice. /guides/checklists/meetings must not be a second URL for the same list. /guides/meetings/meetings must not be a page. Pick an order, generate only that order, and redirect or 404 the other spellings. Otherwise you have published duplicates that differ only by the sequence of folders.
Crawling these URLs still means more work on the server and, potentially, slower discovery of new URLs. A handful of real categories is a reasonable cost. A generated page for every pair of tags is the cost Google is warning you about. Write the category only when it has something to say that the unfiltered list does not. A heading that repeats the filter words is not that something.
Empty combinations return 404
When a combination returns no items, respond with HTTP 404. Google is specific: users and crawlers should get a not-found error with the proper status code. The same applies to duplicate filters, nonsensical combinations, and pagination URLs that do not exist. Do not redirect the empty combination to a common error page. Serve the 404 at the URL that was requested. If you send every miss to /not-found, the filter URL itself never says it is missing. Google asked for the filter. Answer there.
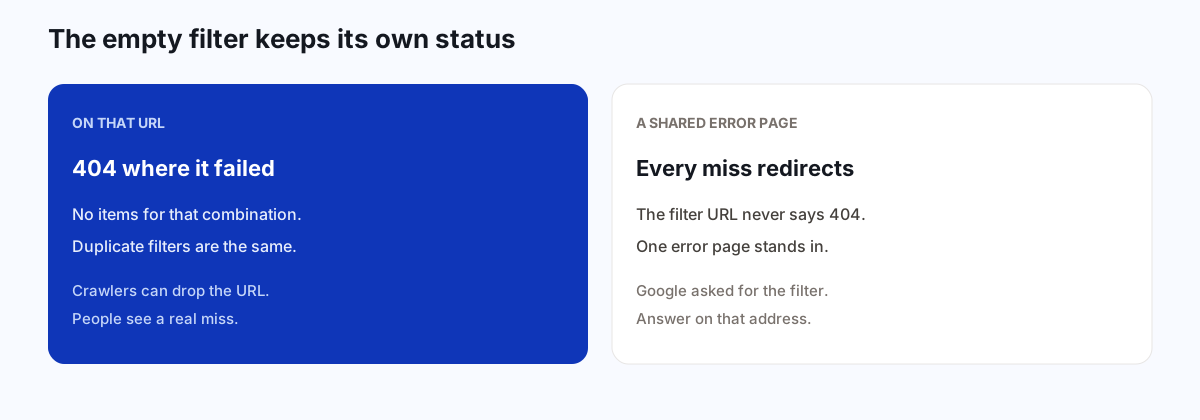
A 200 page that says “no matches” is a soft 404. Google can keep treating it as a real URL. The faceted guide’s 404 rule and the soft-404 guide are the same instinct: the status has to match the body. A single-page app often cannot set that status from the router alone, because every path returns 200. Google points those sites at the single-page-app guidance. The practical version is the JavaScript guide: the server should return 404 for a URL that has no document, instead of painting “nothing matched” on a success code.
Pagination of a real list is not an empty filter. Page 2 of /guides exists when page 2 has items. A request for page 40, when the list ends at page 3, is the nonexistent pagination case, and it should 404. The pagination guide is why page 2 keeps its own canonical when it does exist. Do not disallow ?page= in the same rule you use for junk filters. That hides the sequence.
What this is not
An article with a tracking parameter is not faceted navigation. Canonicalize the tracking copy or stop adding the parameter. A session ID is the URL structure problem, solved with a cookie, not with a filter policy. A sort control on a blog index is closer to this page: it creates another view of the same items. On a normal blog, do not generate that URL. On a very large site already at its fetch limit, the crawl-budget guide is why robots.txt may cover the sort pattern. The faceted guide is the more specific version of that advice for filters.
Do not mark every filter combination noindex and leave the links in place if the site is large and the combinations are endless. Google still has to fetch a noindex URL to see the tag. That is the crawl you were trying to avoid. noindex fits a small set of URLs that must remain reachable and must not be results. Endless filters fit “do not create the URL,” or a disallow of a pattern you also stop linking.
A filter example
Northwind’s guides live at /guides, with each article at its own path. The listing links to the articles. They have one category, /guides/meetings, because that section has its own introduction and people look for it. The path order is section, then topic. They do not also publish /guides/meetings/meetings. A control for “checklist only” updates the list in the page with a fragment, so the address stays /guides/meetings. That filtered view is not in the sitemap and is not a second result.
A request for a combination that matches nothing, including a repeated folder, returns 404 on that URL. It does not 302 to the homepage and it does not 200 with an empty grid. ?page=2 on the meetings list exists only while there is a second page, and it is not disallowed. The articles are not disallowed. They do not expect the category URL to rank because it has three filters in it. They expect the standup guide to be the page that ranks for the procedure.
How this shows up on a blog
BloGoose publishes articles to paths you choose. It does not need a filter URL for every tag pair those articles could share. A category is worth a URL when you will maintain it as a page. A combination that only exists because two tags co-occur is not a brief. Generating those combinations, then asking for a unique article on each, is how a directory becomes a pile of near-duplicates. The scaled content guide is that pile. This page is the crawl side: do not give the pile an address.
If a theme adds query filters by default, turn off the ones that are not real sections. Keep the article links crawlable. One list, the articles, and the few categories you mean. That is the whole faceted decision for a publishing site.
Questions about faceted navigation
What is faceted navigation?
Faceted navigation lets a person change how a list of items is shown, usually with filters. The common implementation puts each filter in the URL. Combinations of those filters can create a very large set of URLs.
Should filter URLs be indexed?
Only if you need those filtered lists in search. If you do not, keep Google from crawling them and let it crawl the items and one unfiltered listing. Crawling every combination uses server resources and can slow discovery of new URLs.
Is robots.txt the right way to block filters?
When you do not need the filtered URLs indexed, Google recommends disallowing those parameter patterns in robots.txt, while still allowing the item pages and the unfiltered list. A disallow is not a reliable way to hide a URL that other sites link to. Do not disallow the articles.
Do fragments make filter pages?
No. Google generally does not crawl a fragment as a separate page. Using a fragment for a filter keeps that filter from becoming another URL. It does not create an indexable filtered page. Use a real path when the filtered list is a page you want found.
Does a canonical tag replace robots.txt for filters?
Not as the main control. Google says a canonical can, over time, reduce crawling of the non-canonical versions, and that this is generally less effective in the long run than disallowing the URLs or using fragments. Use a canonical when the filtered URL should stay available and you want one preferred list.
What status should an empty filter return?
Return 404 on the URL that was requested when the combination has no results, repeats a filter, or is nonsense. Do not redirect that URL to a shared error page. A 200 page that only says nothing matched is a soft 404.
One list, the articles, and only the filters you mean to keep. Empty combinations are 404s.
Start the 1-day trial