A soft 404 is a URL that tells someone the page is missing, empty, or broken, while the server still returns HTTP 200. A custom 404 page is the screen you design for a person who followed a dead link. Google’s crawling-errors documentation, updated 18 December 2025, says a 200 with an error or an empty page is a bad experience, and those URLs are excluded from Search. The fix is the status code, not a prettier message on a successful response.
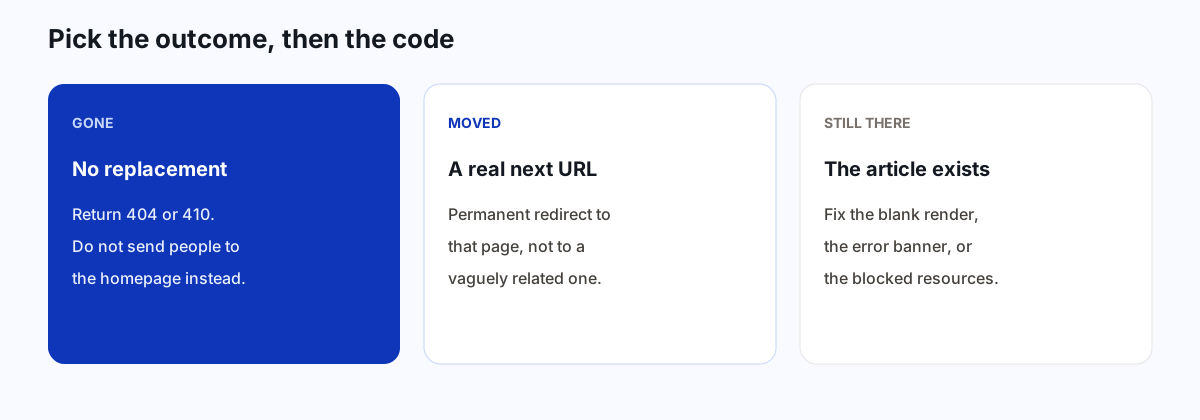
Match the code to the truth. If the article is gone and nothing replaced it, return 404 or 410. If it moved, redirect to that URL. If the article still exists, fix the blank page. A custom message is for the person. It does not replace the status code, and it should not be indexed.
What a soft 404 is
HTTP 200 means the server completed the request and is handing over a page. Crawlers treat that as a candidate for indexing. Google’s status-code documentation, updated 4 February 2026, says a 2xx response is considered for processing, and if the content suggests an error, an empty page, or an error message, Search Console reports a soft 404. The design can say “not found.” The code said “here is a page.”
Google lists ordinary causes: a missing server-side include, a broken database connection, an empty internal search result, or a JavaScript file that never loaded. A blog adds a few more. A deleted post whose theme still renders a friendly empty layout. A tag archive with zero posts. An empty filter combination should return 404 on the URL that was requested, not redirect to a shared error page. The faceted navigation guide is that status. A single-page app that paints “not found” in the browser while the server returned 200. Google’s JavaScript troubleshooting notes that client-side error screens often keep the success code, and those error pages can be indexed. The JavaScript SEO guide is the two documented fallbacks: redirect to a URL that really returns 404, or add noindex from script only when the HTML did not already include it.

Check one URL before you redesign anything. Request the dead address and read the status line. If it says 200, you have the problem this page is about, even when the HTML looks like an error. If it says 404, you already did the important part. The rest is whether the HTML helps a person who landed there.
Search Console’s Page Indexing report is where Google says it will show the soft 404 once its systems decide the page is an error from the content. A report row is a diagnosis. It is not a ranking penalty applied to the rest of the site. The URL itself is what gets excluded. On a large site, that 200 also keeps the URL in the crawl queue. Google’s crawl-budget guide says soft 404s continue to be crawled and waste budget, while a real 404 does not. The crawl budget page is for hosts that are actually that large. The status code is the fix either way.
Gone, moved, or still there
Google’s fix is three branches. Pick the one that matches the URL, then stop.
| State of the URL | What to return | What not to do |
|---|---|---|
| The article is gone, and nothing on the site replaces it | 404 or 410 | A 200 “not found” layout, or a redirect to the homepage |
| The article moved, or a merge left one surviving URL | A permanent redirect to that URL | A redirect to a vaguely related post. The canonical tag is for two addresses of the same document, not for a page you deleted. |
| The article is still the one you want found | 200, with the article actually in the HTML | Turning it into a 404 because Search Console used the soft-404 label |
| The URL should exist and should not be a result, such as a thank-you page | 200, with a robots meta noindex | A 404, which says the URL does not exist |
404 and 410 are both client errors. Google’s status-code page says all 4xx codes except 429 are handled the same way for Search: the indexing pipeline removes a URL that was indexed, newly seen 404 URLs are not processed, crawl frequency for that URL drops over time, and these 4xx codes do not change the site’s crawl rate. 429 is the exception, because Google treats it as the server being overloaded. You do not need a project to convert every 404 into a 410. Use 410 when you mean “gone on purpose.” Use 404 when the address is simply not a page. Either one is a real signal. A 200 is not.
A permanent redirect is the other honest signal, and only when there is a clear replacement. Google says a 301 is a strong signal that the target should be processed, and that crawlers follow a limited number of hops, generally 10 for ordinary web crawling. A chain of three old slugs before the article is a worse map than one hop. Long chains also slow crawling. One redirect, to the page that replaced this one, is the whole job. The difference between a 301 and a 302, and why a chain is worse than one hop, is the redirects guide. The content refresh guide is when the slug itself changed because the old address lied.
What a custom 404 page is for
Google’s design notes for a custom 404 are about people, and they are short. Say clearly that the page cannot be found, in ordinary language. Use the same navigation and look as the rest of the site, so the person knows they are still on your site. Offer a few real articles and a link home. Consider a way to report a broken link. That is the page. It is not a second homepage, a keyword list, or an article about 404 errors that you hope will rank.
The same documentation says custom 404 pages are created solely for users and are useless to a search engine, so the server must return 404 to keep them out of the index. If your theme’s “pretty 404” is a normal template that returns 200, the prettiness is the bug. Style the error. Keep the code.
Keep the error light. The person is already in the wrong place. A 404 that waits on a large script, a font, and a widget before it says “missing” is a slow dead end. The status code and a short HTML message can arrive together. Links in that message should be normal a href links to URLs that return 200, not buttons that only work after JavaScript, and not links back to other missing URLs.
Do not put the only copy of a product explanation on the error page and expect it to be the page that ranks. Google has said, in older notes on 404 content, that a 404 is a poor place to put something you want indexed. Put that explanation on a real URL.
Redirects, noindex, and robots.txt
The common cleanup is the wrong code for a tidy report. A spreadsheet of 404s feels like damage. Redirecting all of them to the homepage makes the report quieter and the site less honest. The homepage is not the replacement for a deleted post about retro questions. A person who wanted that post, and a crawler that wanted that URL, both land on a page that does not answer them. That pattern is how a redirect itself gets treated as a soft 404: the target does not satisfy the URL that was requested.
Redirect the misspellings and the old slugs that have a true destination. Leave the rest as 404. A typo of a live article can redirect to that article. A post you unpublished, with no successor, should not.
noindex is the wrong tool for a URL that does not exist. noindex is an instruction on a page Google fetched. A thank-you page exists. A draft preview exists. A missing article does not. Returning 200 plus noindex asks Google to crawl a page you are also saying is not a page. Return 404 and you do not need the robots tag.
robots.txt is worse for this job. Google only learns the status code by requesting the URL. A disallow stops that request, so the 404 is never observed, and a URL that other sites still link to can remain in results without a clear error. The robots guide is the rule for pages you want hidden. Do not use it to hide the fact that a URL is gone. Do not block the 404 template in a way that turns the response into an empty or blocked fetch.
Do not invent a thin article at the old URL so the 404 goes away. A page that exists only to catch the old query, with little to say, is a different problem, covered in scaled content abuse. A 404 is cleaner than a placeholder.
When a real article is flagged
The third branch is the one people skip. Google says a good page can be flagged if it did not load for Googlebot, if critical resources were missing, or if a prominent error showed during rendering. The URL Inspection tool shows the rendered HTML and the status code. Use it on one flagged article before you delete anything.
Typical causes on a blog: the article body is injected by a script that a robots.txt rule blocks; the first screen is a spinner and the text never arrives in the HTML; a database error is printed above an empty post; the page is so large, or so dependent on a slow file, that the render looks blank. The fix is to put the article in the response, allow the resources that are required to understand it, and remove the error banner. Then request indexing of that URL if you want another look. Do not 404 it to clear the report.
An empty category or tag page can look like the same flag. If the archive has no posts and no explanation, it is close to an empty page. Give it a real job, noindex it if it should not be a result, or stop emitting the URL. A grid of titles with no introduction is not saved by a 200. The content audit is the label for a URL you still publish. A soft 404 is the label for a URL whose response is an error pretending to be a page.
Sitemap and schema
Take the dead URL out of the XML sitemap in the same change as the 404. A sitemap entry asks for a crawl of an address you just said does not exist. After a redirect, list the target, not the old path. Do not list the 404 template itself.
Do not print article schema on the error template. A 404 is not an article. A headline, an author, and a date on “page not found” describe a document that is not there. If the layout wraps every response in BlogPosting, the error page inherits a fake article. The schema should be on the posts, not on the failure.
Internal links should not point at URLs you know are 404. When you remove a post, update the guides that linked to it. A crawler can still discover the old URL from those links and then see the 404, which is fine. A reader should not have to. The citing sources page is the same habit for outbound links: if the document moved, link the document that exists.
What a missing URL should not quote
An answer engine quotes text it can fetch. A soft 404 that returns 200 and a sentence such as “this guide has moved” without the guide, or a keyword paragraph written to replace the missing post, is a page a system can cite by mistake. The citation will be the error, or the placeholder. A real 404 gives the fetcher an empty result instead of a fake article. That is the useful outcome for both Search and any system that reads the URL.
Do not hide the answer inside the 404 and hope the status code is ignored. Do not add FAQ markup to the error page so it looks like a guide. The questions people have belong on the article that answers them.
A soft 404 example
Northwind unpublished /retro-questions-2019. The theme still renders the site header, a drawing of a lost goose, and the sentence “We could not find that page,” and the server returns 200. The URL is still in the sitemap. Search Console lists it as a soft 404. Nothing on the site replaced that post. The year in the slug was the reason they removed it.
The fix is a 404 status on that URL, the same short message and a link to the current retro guide if they have one that actually replaces it. If they do not, the links are the homepage and two current articles, not a redirect of this URL to the homepage. The sitemap line is deleted. The template does not emit article schema. A request shows 404.
/status-meetings is a different row. That slug was renamed, and /async-standups is the article. That URL redirects. It is not a soft 404, and it should not become one by “simplifying” every old path to the same error page.
/async-standups itself should never be in this report. If it appears, they inspect the rendered HTML. The procedure should be in the response, not behind a script the crawler did not run.
How this shows up when BloGoose reads a site
BloGoose reads the sitemap and the pages it lists. A URL that returns a not-found layout with status 200 looks like a page with almost no article. It can be proposed as a gap, or treated as a thin URL you already published. Neither is right. The address is a broken response. Fix the code, remove it from the sitemap, and the next read of the site sees the articles that exist.
When you unpublish a post, confirm the public URL returns 404 before you plan a replacement. If you are merging it into another guide, redirect first, then point internal links at the survivor. A new draft should not target a path that still answers with an error.
Questions about soft 404s
What is a soft 404?
A soft 404 is a URL that tells the visitor the page is missing, empty, or broken, while the server returns HTTP 200. Google can exclude that URL from Search and report it in Search Console. A real 404 returns a 404 or 410 status code.
Do 404 errors hurt rankings?
A real 404 tells Google the URL does not exist. Google’s status-code documentation says 4xx responses, other than 429, do not change the crawl rate, and an indexed URL that starts returning 404 is dropped from the index over time. A pile of 404s is not a reason to redirect every missing URL to the homepage.
Should you redirect every 404 to the homepage?
No. Redirect when the page has a clear replacement, such as a merged article at a new URL. The homepage is not a replacement for a deleted post. A redirect to an unrelated page can itself be treated as a soft 404.
What is a custom 404 page?
A custom 404 page is the HTML people see when a URL is missing: a clear message, the site’s navigation, and links to pages that exist. It is for people. The server must still return 404, or Google may index the error page.
Should a 404 be noindex or blocked in robots.txt?
No. Google has to fetch the URL to see the 404. A robots.txt disallow prevents that fetch. noindex is for a page that exists and should not be a result, such as a thank-you page. A URL that does not exist should return 404.
What if a real article is flagged as a soft 404?
Then the page probably looked empty or showed an error when Google rendered it. Check the URL in Search Console’s inspection tool. A blocked script, a failed database call, or a blank first screen can cause the flag. Fix the page. Do not 404 an article you still want found.
Publish URLs that return the article. Let missing ones return 404.
Start the 1-day trial