Pagination splits a long list across numbered URLs so the first screen stays short. rel next and rel prev were the old HTML hint that those URLs belonged to one sequence. Google’s pagination guide says it no longer uses those tags. What it documents now is simpler: give each page its own URL, link from one page to the next with a normal anchor, and do not tell Google that page 2 is a copy of page 1.
Page 2 is a page. Canonicalize it to itself. Put a real “next” link in the HTML. Leave rel next in place only if some other system still reads it. Do not noindex the sequence, and do not hide the rest of the posts behind a button crawlers never press.
What pagination is
Google describes three ways to show part of a long list. Pagination uses links such as next, previous, and page numbers, and each click loads another URL. Load more keeps one URL and adds items when someone clicks. Infinite scroll keeps one URL and adds items when someone reaches the bottom. Pagination’s downside, in Google’s own table, is that the list is split and each step is a new page load. Its advantage is that a person can see how long the list is and where they are in it.
The same guide names the lists this applies to: category pages, blog post titles accumulated over time, reviews, and comments. A company blog’s index is the case on this page. One article chopped into “page 1 of the guide” and “page 2 of the guide” is a different choice. People do better with the whole article on one URL. If you do split an article, do not point every part at part 1. The article schema note on multi-part pages is that decision. This page is the list of posts.
Splitting the list is also a speed choice. Google lists a faster first load, less data on a phone, and a smaller database query as reasons to show a subset. That only helps if page 1 is actually light. A first page that still downloads every post in a hidden script, then reveals ten of them, did not split anything. Send ten posts in the HTML. Link to the URL that contains the next ten.
What happened to rel next
For years, templates put link rel="next" and link rel="prev" in the head and treated that pair as the way to “consolidate” a series. Google’s current guide says it used those tags in the past and no longer uses them. Other search engines may still read them. Browsers may use them to prefetch. Leaving the tags in does not create a Google problem, and removing them does not create one either. They are not the fix if page 2 is canonicalized to page 1, and they are not a substitute for a visible next link.
A plugin screen that scores you down for a missing rel next tag is scoring an old instruction. Check the live head if you want to know what you emit. Then check whether a person can click from page 1 to page 2 without JavaScript. That click is the instruction Google’s guide still gives.
Each page keeps its own canonical
Google is direct: do not use the first page of a paginated sequence as the canonical page. Give each page its own canonical URL. URLs in the sequence are separate pages. A ?page=2 address is a normal way to make that separation. A fragment such as /blog#page=2 is not, because Google ignores the text after # and may treat the “next” link as the same page it already fetched.
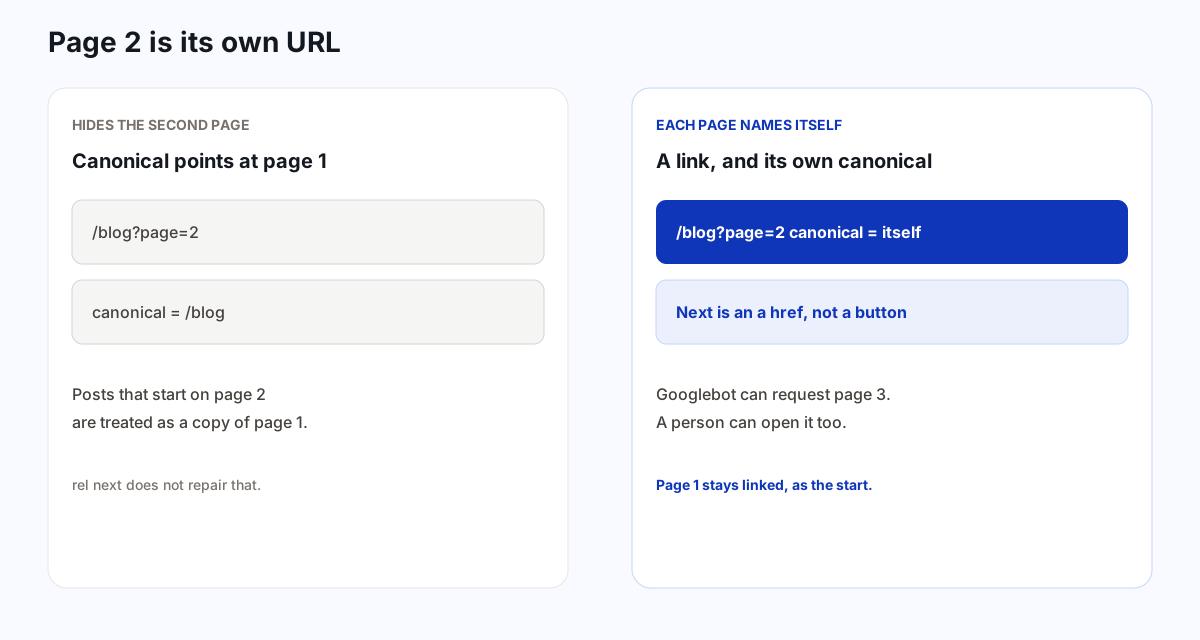
Pointing page 2 at page 1 feels like duplicate control. The posts on page 2 are not on page 1. The canonical tag is for the same document at two addresses, such as a tracking parameter on one article. Two slices of a list are not that document. If you collapse them, Google is asked to drop the slice. Links on page 2 that only exist there become harder to find.
Page 1 should canonical to page 1, with no ?page=1 duplicate if you can help it. If both /blog and /blog?page=1 return the same first screen, pick one, redirect the other, and use the survivor in the next and previous links. Two addresses for page 1 is an ordinary duplicate, not a pagination feature.
Link the pages in order
Google asks you to link each page to the following page with an a tag, so Googlebot can find the later URLs. It also suggests linking each page back to the first page of the collection, as a hint that the first page may be the better landing page. That hint is not a canonical tag. Page 2 can still be indexed. The link to page 1 tells Google where the series starts.
Use the clean URL in those links. A next link that adds a campaign parameter creates another address for the same slice. How parameters should be encoded, and why stacked filters multiply URLs, is the URL structure guide. A page number is a parameter the sequence needs. The canonical on that parameterized URL, if someone requests it, should still be the clean ?page=2, and your own template should not be the thing generating the parameter. Numbered links, not only next and previous, help a person jump. They also give a crawler more than one hop. You do not need a link to every page from every page. Sequential is the requirement. A few extra numbered links are a courtesy.
The link has to be in the HTML response. A control that looks like “next” and only works after a script rewrites the list is the load-more pattern with pagination’s label. View the source of page 1 and search for page=2. If it is not there, Googlebot’s first pass does not have the URL. A fragment such as #/page-2 is not a substitute path. The JavaScript SEO guide is why a real URL, not a hash, has to carry the next view.
Load more and infinite scroll
Google’s crawlers find URLs in the href of anchors. They do not click buttons. They generally do not run a function that waits for a person to scroll or to press “load more” before the next items exist. Infinite scroll and load more are usually built that way. The first screen can be indexed. The rest waits on an action that does not happen during the crawl.
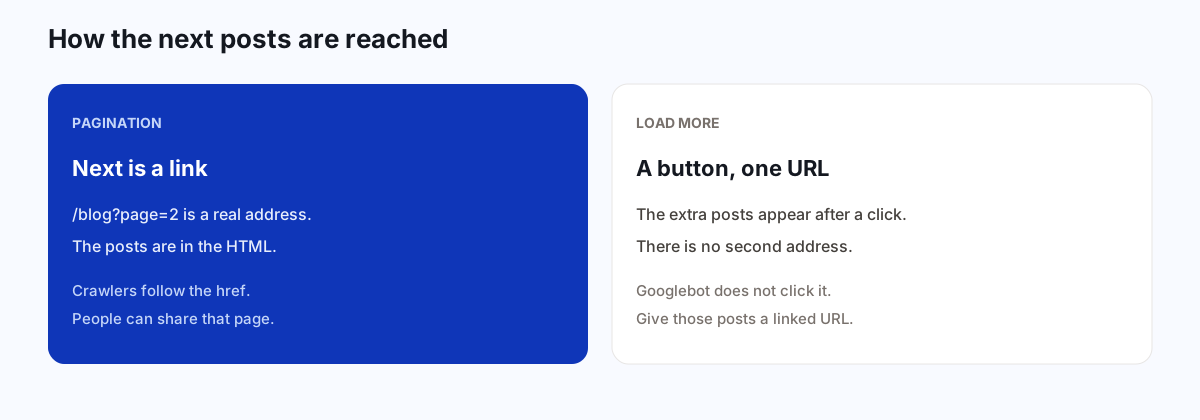
You can still use load more for people if each batch also has a URL. The pattern that works is a paginated series underneath the scroll: the page shows items, and the HTML also links to the next page URL. A crawler follows the link. A person can share page 3. An answer engine that does not run the script can still read the posts that were in the response.
A single URL that grows without a next link has a second problem. Google notes that load more and infinite scroll cannot handle very large lists, because everything ends up on one page. A blog that has published for years will hit that. Pagination keeps each response to one slice. That is the page-experience side of the same decision: less HTML on the first view, and a crawlable path to the rest.
Titles on a sequence
Google normally wants distinct titles so pages are easy to tell apart. For a paginated sequence it makes an exception: you can use the same titles and descriptions on every page in the sequence. Google tries to recognize the sequence and index the pages accordingly. Adding “page 2” to the title is still a kindness to a person who has both results open. It is not required by that paragraph.
The exception is the sequence, not the rest of the site. Two articles that answer different questions still need their own titles. Copying one meta description across unrelated posts is the problem the title tag page describes. A blog index and its page 2 are allowed to share a description because they are one list, continued.
Do not stuff page 2’s title with a keyword the slice does not discuss. The slice is “older posts,” not a second article about standups. If you want a landing page about standups, that is a guide, not ?page=4.
Filters and sort orders
A sort or a filter can create another URL for the same posts in a different order, such as ?page=2&order=oldest. Google says to avoid indexing those variants. The tools it names are a noindex robots meta tag, or a robots.txt rule that discourages crawling of the pattern.
Those two tools are not equal. noindex is read on a page Google can fetch, and it asks that the URL not be a result. A disallow stops the fetch, and a URL that is blocked can still be indexed from links elsewhere, without its content. The robots meta page is that distinction. For a sort URL you do not want as its own result, noindex is the clearer instruction, and the clean paginated URL should remain crawlable. Do not disallow ?page= itself. That hides the sequence you just built. On a very large site, the extra sort URLs are the inventory problem in the crawl budget guide. A normal blog still handles them with noindex, or by not generating them.
Stacked filters that change which items appear are faceted navigation, which is a different problem from a page number the sequence needs. If the filter is the same list, you can also refuse to give it a separate URL and sort on the page without changing the address. Fewer URLs is the smaller fix. Canonicalizing every sort back to page 1 repeats the mistake in the first figure.
Sitemap and page 2
Google finds page 2 from the link on page 1. The XML sitemap can list the blog index. Listing every ?page= URL is optional. Do not list the filter variants. Do not set lastmod on page 2 to “now” every time any post is published, unless you actually know the slice changed and you will keep that date honest. A shifting archive is a poor place for a guessed date. Omit lastmod there if the only clock you have is the sitemap rebuild.
Do not list a page number that 404s because you deleted posts and the count shrank. A next link that points at a missing page is a broken path. When the last page disappears, the previous page’s next link should disappear with it. A soft 404 that returns 200 and “no more posts” is the wrong end of the sequence. The last page simply has no next link.
A pagination example
Northwind’s index is https://northwind.example/blog. It shows the ten newest posts, in HTML, with a next link to /blog?page=2 and numbered links for the pages that exist. Page 2 canonicalizes to /blog?page=2. Its title can be “Northwind blog” or “Northwind blog, page 2.” Both are allowed. The description can match page 1. Each page links back to /blog.
/blog?page=1 redirects to /blog. /blog#2 is not used. /blog?page=2&order=oldest is noindex, or it is not generated. rel next may still be in the head because the theme emits it. Nobody treats that tag as the thing that ties the series together. The anchor does that.
The standup guide is not paginated. It lives at one URL. Comments under it, if there are enough to split, follow the same rules as the index: a next link, a canonical that names that comment page, and no canonical back to the article that would hide the later comments. If there are only a few comments, they stay on the article.
How this shows up on a blog index
When BloGoose publishes, the new post belongs on the first page of the index your site already has. It should not become a new index URL, and it should not depend on a script to appear in the list. After the first posts fill a page, confirm in the browser, with JavaScript disabled or with “view source,” that page 2’s address is an href on page 1 and that page 2’s canonical is page 2.
A theme that infinite-scrolls the home page and never emits ?page=2 will look complete in a demo and incomplete to a crawler. Turn on the numbered links, or add them beside the scroll. The scroll can stay for people. The link is what gets the older titles found.
Questions about pagination
What is pagination?
Pagination is splitting a long list across numbered URLs, with links such as next, previous, and page numbers. Each URL shows one slice of the list. Google treats those URLs as separate pages.
Does Google use rel next and rel prev?
No. Google’s current pagination guide says it no longer uses rel next and rel prev. Other search engines may still read them. The signal Google documents now is an ordinary link from each page to the next page.
Should page 2 canonicalize to page 1?
No. Give each page in the sequence its own canonical URL. Pointing page 2 at page 1 tells Google the second page is a duplicate of the first, which hides posts that only appear on page 2.
Should you noindex paginated pages?
Not by default. Page 2 is a real URL with its own posts. noindex is for a URL that should not be a result, such as a filtered or re-sorted copy of the same list. The robots meta guide is that decision.
Can infinite scroll replace pagination?
Only if the additional items also exist at crawlable URLs. Google’s crawlers do not click a load-more button, and they generally do not run a script that waits for a person to scroll. A next link with a real href is how page 2 gets discovered.
Can paginated pages share a title?
Yes. Google says pages in a paginated sequence do not have to follow the usual advice to give every URL a distinct title and description. Unrelated articles still need their own. The title tag guide is that rule.
Keep the first screen short. Give the next screen its own address.
Start the 1-day trial