
An automated CMS export checklist for SEO teams
Every week, SEO teams publish automated articles that look perfect in preview, then go live with stripped title tags, broken schema, and images pointing to staging URLs. You've probably caught one of these failures only after Google already crawled the damage. That's the silent cost of trusting an export pipeline without a verification layer.
You're right to feel uneasy about hitting "publish" on content you never manually inspected. The promise here is simple: by the end of this article, you'll have a repeatable automated CMS export checklist that catches corruption before it reaches your live site, not after. We'll walk through the five silent failure modes that break automated exports, then give you a 12-point audit you can run in under 20 minutes, and finally show you how to automate the checklist itself so it runs on every export without human babysitting.
Here's the part most guides skip: the #1 failure mode isn't broken images or missing alt text. It's metadata stripping, and it happens in the export layer, not in your CMS. We'll show you exactly where to look. Tools like BloGoose already bake export validation into their publishing pipeline, but even if you're stitching together your own stack, the checklist below works standalone.
What Are the 5 Silent Failure Modes in Automated CMS Exports?
An automated CMS export is the process of moving content from a drafting or generation system into a live content management system through an API, plugin, or file transfer, and it fails silently when the export layer drops, rewrites, or corrupts data without throwing an error. Think of it like a photocopier that occasionally removes the page numbers: the copy looks fine until you try to cite it.
These five failure modes account for nearly every export-related SEO regression. Each one degrades search visibility without triggering a visible alert in your CMS dashboard.
1. Metadata Stripping
Metadata stripping happens when the export layer doesn't map custom fields, title tags, meta descriptions, and canonical URLs get dropped entirely. Your CMS falls back to auto-generated titles or leaves the canonical tag empty. Symptom: pages go live with duplicate or truncated titles in search results. SEO impact: canonical URL integrity breaks, splitting ranking signals across duplicate URLs. This is the #1 failure mode because it's invisible in the visual editor, you only see it in the page source.
2. Schema Block Corruption
Schema block corruption occurs when JSON-LD passes through an API export layer that escapes quotes, strips the @type property, or wraps the entire block in invalid markup. Symptom: Google's Rich Results Test throws "Unspecified Type" errors. SEO impact: you lose eligibility for rich snippets, FAQ results, and AI answer citations. Always run schema markup validation on exported pages, not just on the source draft.
3. Image Tag Degradation
Image tag degradation is what happens when relative src paths (/images/post. jpg) aren't converted to absolute URLs (https://yoursite.com/images/post.jpg) during export. Alt text also gets dropped when the export layer only maps the src attribute. Symptom: broken images in RSS feeds, social shares, and Google Discover. SEO impact: image search traffic collapses and accessibility scores drop.
4. Internal Link Rewriting
Internal link rewriting breaks link equity when the export layer converts absolute internal URLs to relative ones, or vice versa, inconsistently. A link that works in the staging preview may 404 on production because the path resolution changed. Symptom: crawling tools like Screaming Frog report a spike in broken internal links after each export batch. SEO impact: PageRank flow through your site architecture gets interrupted at exactly the wrong nodes.
5. HTML Entity Escaping
HTML entity escaping failures happen when quotes, ampersands, and special characters get double-escaped, & amp; instead of &, rendering as visible code in your published text. Symptom: readers see & quot; in headlines and body copy. SEO impact: Google may interpret the malformed entities as thin or spammy content, and featured snippet eligibility drops.
Here's the self-contained answer to the question most SEO teams ask: Which export failure causes the most ranking damage? Metadata stripping. When title tags and canonical URLs are dropped, Google re-crawls the page and sees a different identity than the one that earned rankings. The page effectively competes against itself, the old indexed version and the new stripped version split signals until Google picks one, often the wrong one. Unlike broken images or schema errors, which are visible in testing tools, metadata stripping requires viewing the raw HTML source of the exported page. Teams that only check the visual preview never catch it.
How to Run the 12-Point Automated CMS Export Checklist
The 12-point automated CMS export checklist is a four-bucket audit, metadata, schema, images, and links/formatting, that verifies every exported article matches its source before it goes live. Run it on a staging environment first, then apply the same checks to production exports.
Prerequisites: access to your CMS staging environment, a browser with View Source enabled, a JSON-LD validator (Google's Rich Results Test works), and the source draft for diffing. Budget 20 minutes per export batch.
Bucket 1: Metadata (Items 1 - 3)
- Check title tag length. Open the exported page source and locate the
< title>tag. Confirm it's between 50 - 60 characters and matches the source draft exactly. You should see the same title you wrote in the drafting tool, not a truncated or auto-generated fallback. For reference on optimal formatting, review title tag length best practices. - Verify meta description presence. Locate the
< meta name="description">tag. Confirm it exists, falls between 140 - 155 characters, and wasn't dropped during export. A missing description means Google will auto-generate one, often from the wrong paragraph. - Confirm canonical URL match. Check the
< link rel="canonical">tag points to the exact live URL of the exported page, not the staging URL, not the source draft URL. A mismatch here splits ranking signals immediately.
Bucket 2: Schema (Items 4 - 6)
- Run a JSON-LD parse test. Copy the
< script type="application/ld+json">block from the exported page and paste it into Google's Rich Results Test. You should see "No issues detected", not a parse error. - Verify @type preservation. Confirm the
@typeproperty (e. g.,Article,BlogPosting) survived the export intact. If it's missing or changed toThing, the export layer stripped it. - Check required properties. For Article schema, confirm
headline,author, anddatePublishedare all present and populated. Missing any one of these disqualifies the page from rich results.
Bucket 3: Images (Items 7 - 9)
- Confirm alt text presence. Inspect each
< img>tag in the exported HTML. Every image should have a non-emptyaltattribute matching the source draft. Empty alt attributes are a silent export failure. - Resolve src URL paths. Verify every
srcattribute uses an absolute URL (https://yoursite.com/images/...), not a relative path. Relative paths break in RSS feeds, email clients, and social share previews. - Check aspect ratio preservation. Confirm the exported image dimensions match the source. If the export layer resized or cropped images, you'll see layout shifts and potential Core Web Vitals penalties.
Bucket 4: Links & Formatting (Items 10 - 12)
- Validate internal link href integrity. Click or crawl every internal link in the exported article. Each
hrefshould resolve to a 200-status live URL, not a staging URL, not a 404. Broken internal links leak equity and frustrate crawlers. - Check HTML entity rendering. Search the exported page for visible entity codes like
& amp;,& quot;, or'. You should see clean rendered characters, ampersands, quotes, apostrophes, not raw code in the visible text. - Verify heading hierarchy. Confirm the exported page preserves H1 to H2 to H3 structure without skipping levels. A page with an H1 followed by an H4 signals a corrupted export and confuses both readers and crawlers.
Dry-run export protocol: before routing any batch to production, export to staging first, run all 12 checks against the staging copy, diff the staging HTML against the source draft, and only then push to live. This contrarian step adds 10 minutes but catches failures that would otherwise require a crawl-and-recovery cycle. For a full reference on publishing standards, see this SEO publishing checklist.
Here's the self-contained answer to the most common follow-up question: How often should you run the 12-point checklist? Run it on every export batch, not just the first one. Export pipelines change, plugin updates, API version bumps, and CMS migrations all introduce new failure modes. A batch that passed last week can fail this week if your CMS updated its REST endpoint or your export tool changed its field mapping. Teams that run the checklist only once are auditing a snapshot, not a pipeline. The dry-run protocol exists precisely because export behavior is not stable over time.
Once you've run this checklist manually a few times, you'll notice the same checks repeating, which means it's time to automate the checklist itself.
How to Automate the Checklist Itself
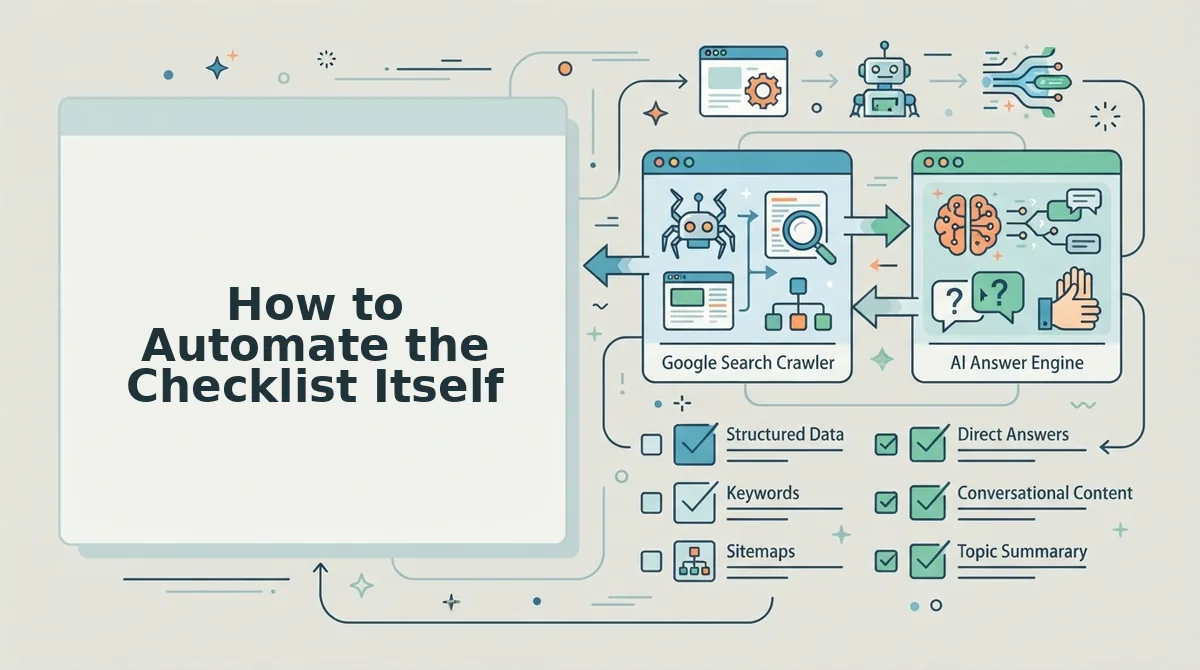
You can turn the 12-point export checklist into a repeatable validation pipeline that runs in minutes, not hours. The key is pairing a validation script with a diff tool so every export gets checked the same way, every time.
Prerequisites: Access to your CMS export file (HTML or JSON), a code editor or terminal, Node. js or Python installed, and a diff tool like Beyond Compare, Kaleidoscope, or Git diff.
- Export your staging content to a local folder. Use your CMS's native export feature or a CLI tool like WP-CLI for WordPress. Save the raw HTML files to a dedicated
exports/directory. You should see one file per page or post, named by slug. - Write a validation script that parses each exported HTML file. Use a Node. js script with Cheerio or a Python script with BeautifulSoup. Have it check for: canonical URL presence in
< link rel="canonical">, JSON-LD schema blocks with required properties, alt text on every< img>tag, and internal link hrefs that resolve to live URLs. Each check should log a pass or fail per page. - Run the script against the export folder. Type
node validate-export. jsorpython validate_export. pyin your terminal. You should see a per-page report listing green checkmarks for passed checks and red X marks for failures, with the specific file and line number for each failure. - Diff the staging export against your source content. Open your diff tool and compare the exported HTML files against the original drafts or the live staging pages. Look for silently stripped metadata fields, missing schema blocks, and altered heading structures. Any difference that is not an intentional change is a silent failure.
- Schedule the validation script to run on every export. Add it as a pre-publish hook in your CI pipeline or a cron job that runs after each CMS export. You should receive a pass/fail summary in your terminal or Slack before any content reaches production.
Validation scripts can parse JSON-LD, check alt text presence, and verify canonical URLs in bulk across hundreds of pages in under a minute. Diff tools compare the staging export against source content to catch silent failures that scripts miss, like a stripped meta description or a reformatted heading. Manual review still wins for brand voice, contextual relevance, and visual layout checks, no script can tell you if a paragraph sounds like your brand or if an image is placed correctly. The smart workflow is: automate the mechanical checks, then spend human review time on the judgment calls. BloGoose's automated blog publishing engine bakes export validation into its pipeline, so the 12 checks run automatically before every article ships.
Frequently Asked Questions About Automated CMS Export Checklists
An automated CMS export checklist is a repeatable set of validation checks, metadata, schema, images, links, and formatting, that runs against every content export to catch silent failures before they reach a live site.
What items belong on an automated CMS export checklist for SEO publishers?
Metadata fields, schema blocks, inline image tags, internal links, and HTML formatting. Each item needs a specific pass/fail check: canonical URL present, JSON-LD parses, alt text exists, internal hrefs resolve, and heading structure remains intact.
How do I verify schema markup survived a CMS export?
Parse the JSON-LD in the exported HTML and check for required properties. Use a script to extract every < script type="application/ld+json"> block, validate the JSON syntax, and confirm required fields like headline, author, and datePublished are present.
What's the most common metadata field that gets stripped during export?
Canonical URL, because it often lives in a custom field that export layers ignore. Many CMS export tools only pull the main content body and standard fields, leaving custom meta boxes behind. Always check the canonical tag explicitly in your validation script.
Should I export to staging before routing to production?
Yes, a dry-run export to staging lets you diff against source and catch failures before they hit live. Run the full 12-point checklist on the staging export, fix any failures, then push the verified content to production.
Why does my CMS export sometimes drop internal links or image alt text?
Export layers often strip HTML attributes they do not recognize, including alt text and custom link classes. Some CMS platforms serialize content through a sanitizer that removes attributes not in an allowlist. A validation script that checks for alt text presence and internal link hrefs catches this immediately.
For a deeper walkthrough of export QA, see our guide to CMS export QA.
From Checklist to Autopilot: Closing the Export Integrity Loop
The Export Integrity Audit framework works because it treats every export as a release candidate, not a finished product. The 12-point checklist catches the mechanical failures, stripped canonicals, missing schema, broken internal links, while the diff step surfaces the silent changes that scripts cannot flag. Those still need a human eye, and they always will.
That is the real insight from this framework: automation does not replace review, it relocates it. Scripts handle the repetitive verification, and your team spends review time on the decisions that actually affect rankings and reader trust. The next step is to run the 12-point checklist manually on your next export, then script the mechanical checks so they run automatically. BloGoose's AI SEO content engine includes export validation as part of its publishing pipeline, and its AEO content optimization tool ensures your schema and metadata survive every export. Start with one export, one checklist, and one script, then let the pipeline do the rest.